Inside Arlo
How we built a compliance-first AI investing assistant
Why we built Arlo
Since dub’s founding, our mission has been to enable anyone to invest like the experts. For too long, expert investing and quality investment advice have been limited to the ultra-wealthy.
Our first product, copy trading, changed that. Instead of picking their own stocks, anyone could copy the investments of other dub members, users with real track records who today include hedge fund managers, investment advisers, and popular investing voices on X and Seeking Alpha.
It resonated: more than 2 million people downloaded dub in our first two years.
When AI agents crossed a capability threshold late last year with Claude Opus 4.5, we saw a chance to push that mission much further. Could we build an AI financial assistant that gives personalized investment advice and fills the gaps copy trading inherently can’t fill?
Arlo is our first big step toward that. Now anyone with Arlo can start tapping into financial wisdom previously limited to those who can afford a wealth manager.
You might ask: can’t Claude do this on its own? We wondered the same thing on day one. In fact, Arlo runs on Claude. But Claude alone, however capable, doesn’t know a member’s holdings, their risk profile, or the rules an investment adviser has to follow. On its own, a model can state things it can’t support, or lean toward being helpful over being right. When it comes to your hard-earned money, that isn’t good enough. There’s a good reason securities law exists, and a good reason human money managers must pass exams and follow it.
Closing that gap is the hard part. It takes account data, suitability checks, rule packs grounded in SEC and FINRA requirements, and human review of the model’s behavior. Making all of that work, and then giving good advice on top of it, is what the rest of this post is about. And we’re just getting started.
The problem: every investor asks differently
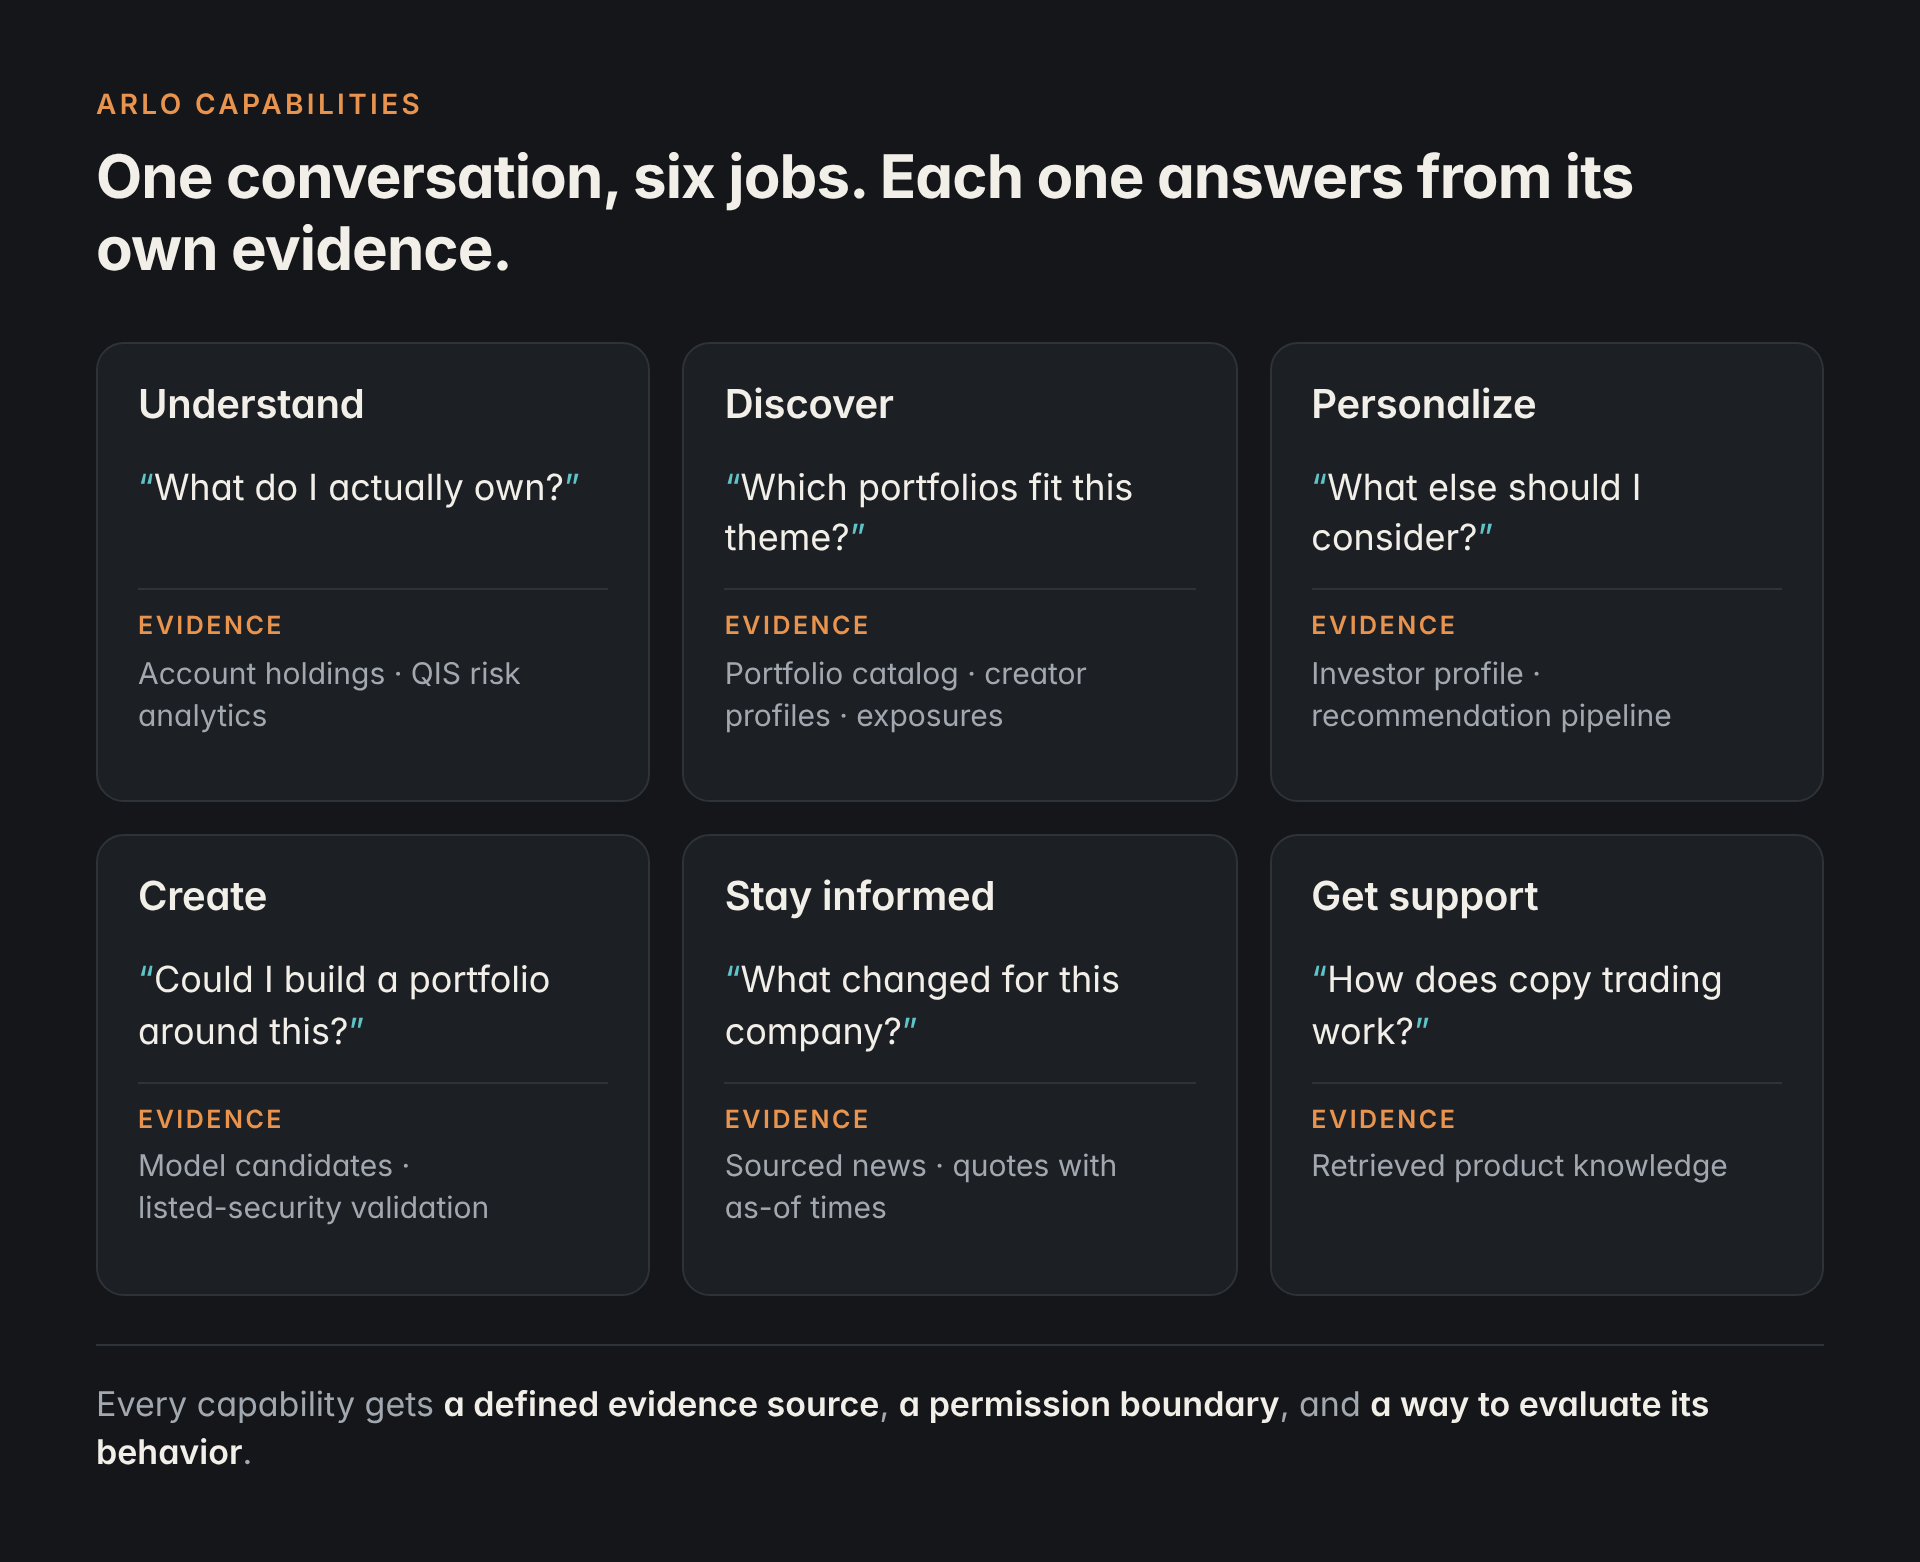
One investor starts with “What do I actually own?” Another wants to know “How much exposure do I have to this theme?” A third skips straight to “What else should I consider?” or arrives with an idea: “Could I build a portfolio around this?”
Answering well takes account context, current data, an understanding of the investor, and clear limits on what the system can say and do.
Arlo brings investment insights, discovery, personalized recommendations, market intelligence, support, and portfolio creation into one conversation inside dub. Underneath, every capability gets a defined source of evidence, a permission boundary, and a way to evaluate its behavior.
Routing, capability resolution, and prompt composition
Our first version of Arlo was a single monolithic prompt. Each new capability added more instructions, more tool definitions, and more domain knowledge to the same context. It worked at first. Then the context grew toward 200k tokens, and it became unwieldy:
- Instructions for one task bled into others.
- A small edit could change behavior somewhere unrelated.
- It was hard to say which rules applied to a given answer.
- Every request paid the cost of the full context.
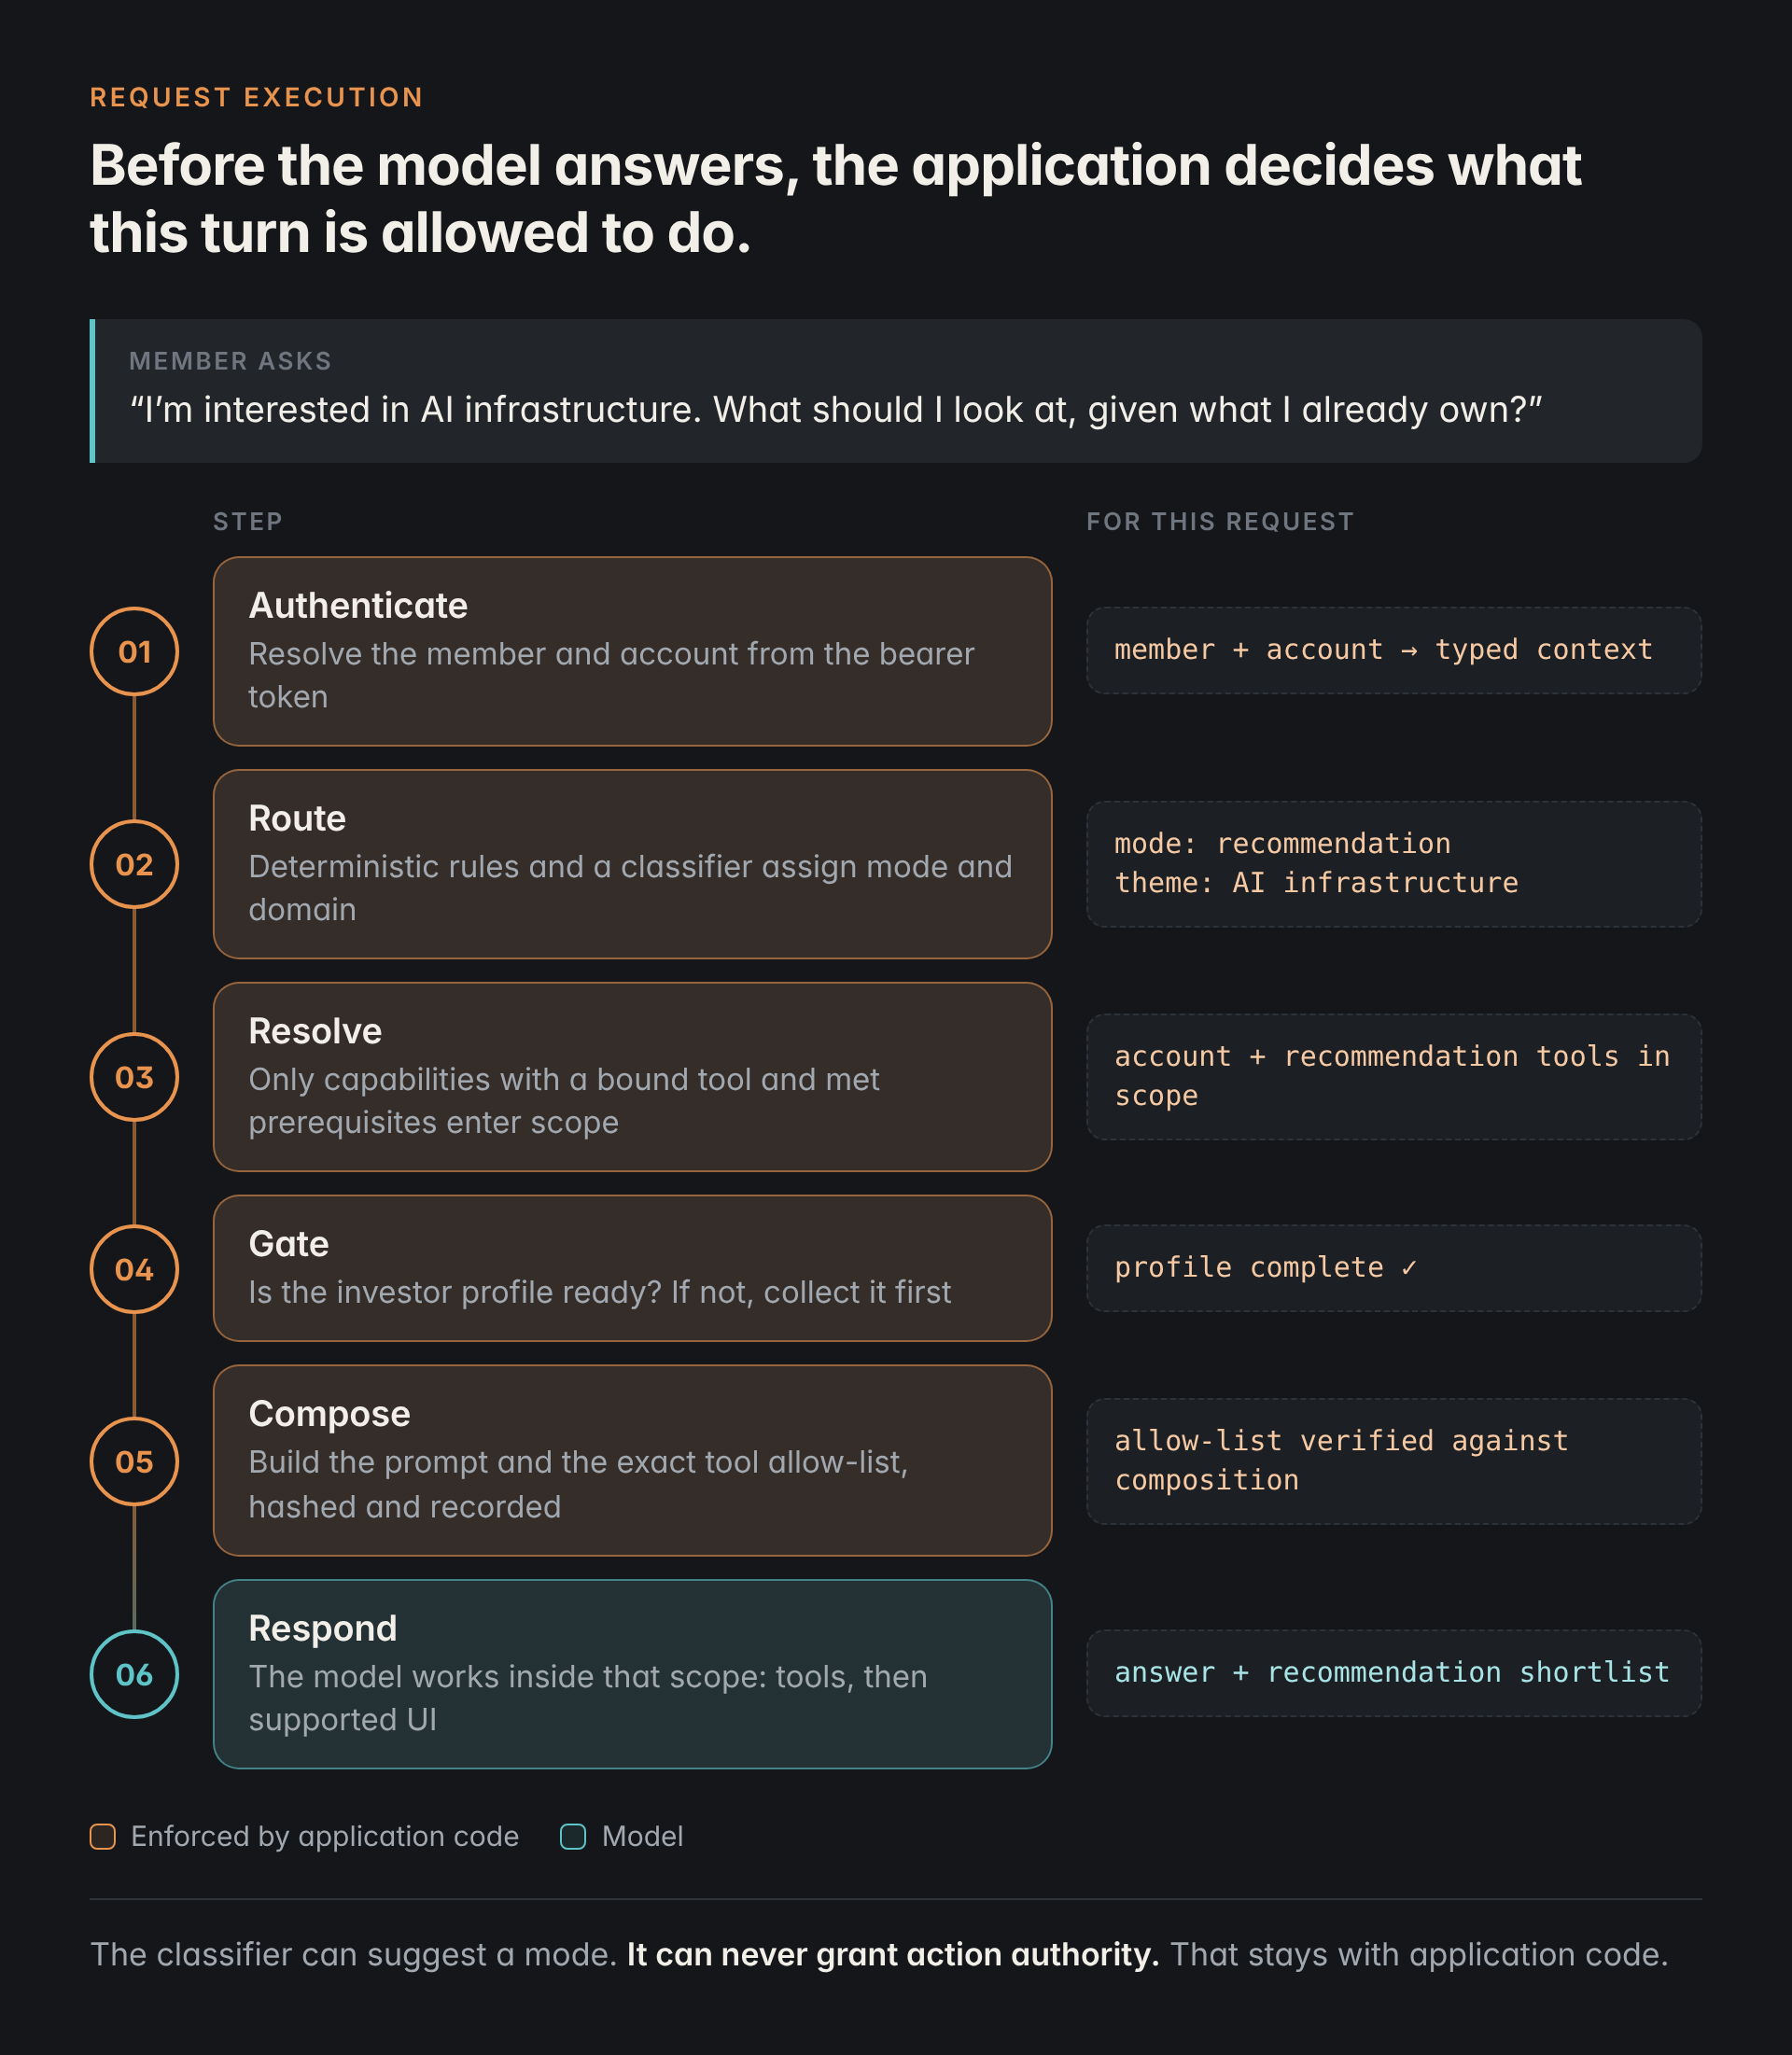
We replaced it with an intent-based, composable system. Arlo first decides what a turn is for. It then assembles only the playbooks, tools, and knowledge that turn needs, and records exactly what it used.
Before the model responds, the application establishes what this turn is allowed to do.
For example, take “I’m interested in AI infrastructure. What should I look at, given what I already own?” Arlo has to recognize a recommendation request, keep the theme intact, confirm the investor profile is ready, and work out which account and recommendation capabilities are available.
Routing. Deterministic rules and a structured model classifier assign a response mode and domain. The classifier alone can never grant action authority.
Capability resolution. Working from a closed readiness snapshot, a capability enters scope only if it has a bound tool and its prerequisites are met. If a required capability can’t resolve, Arlo falls back to core behavior.
Prompt composition. The composer assembles identity, compliance, style, playbooks, tool and UI contracts, and relevant knowledge into a request-specific prompt, recorded with a content hash and selection metadata. The graph then checks that the model’s tool allow-list matches the composition. An intentionally empty list stays empty.
Application code enforces which tools a turn can use. Response contracts define how results should be explained, and evaluation tests them. Keeping those separate makes the system easier to reason about.
A comparison, a recommendation, and an action request carry different evidence requirements and different authority.
Playbooks, capabilities, and the stack
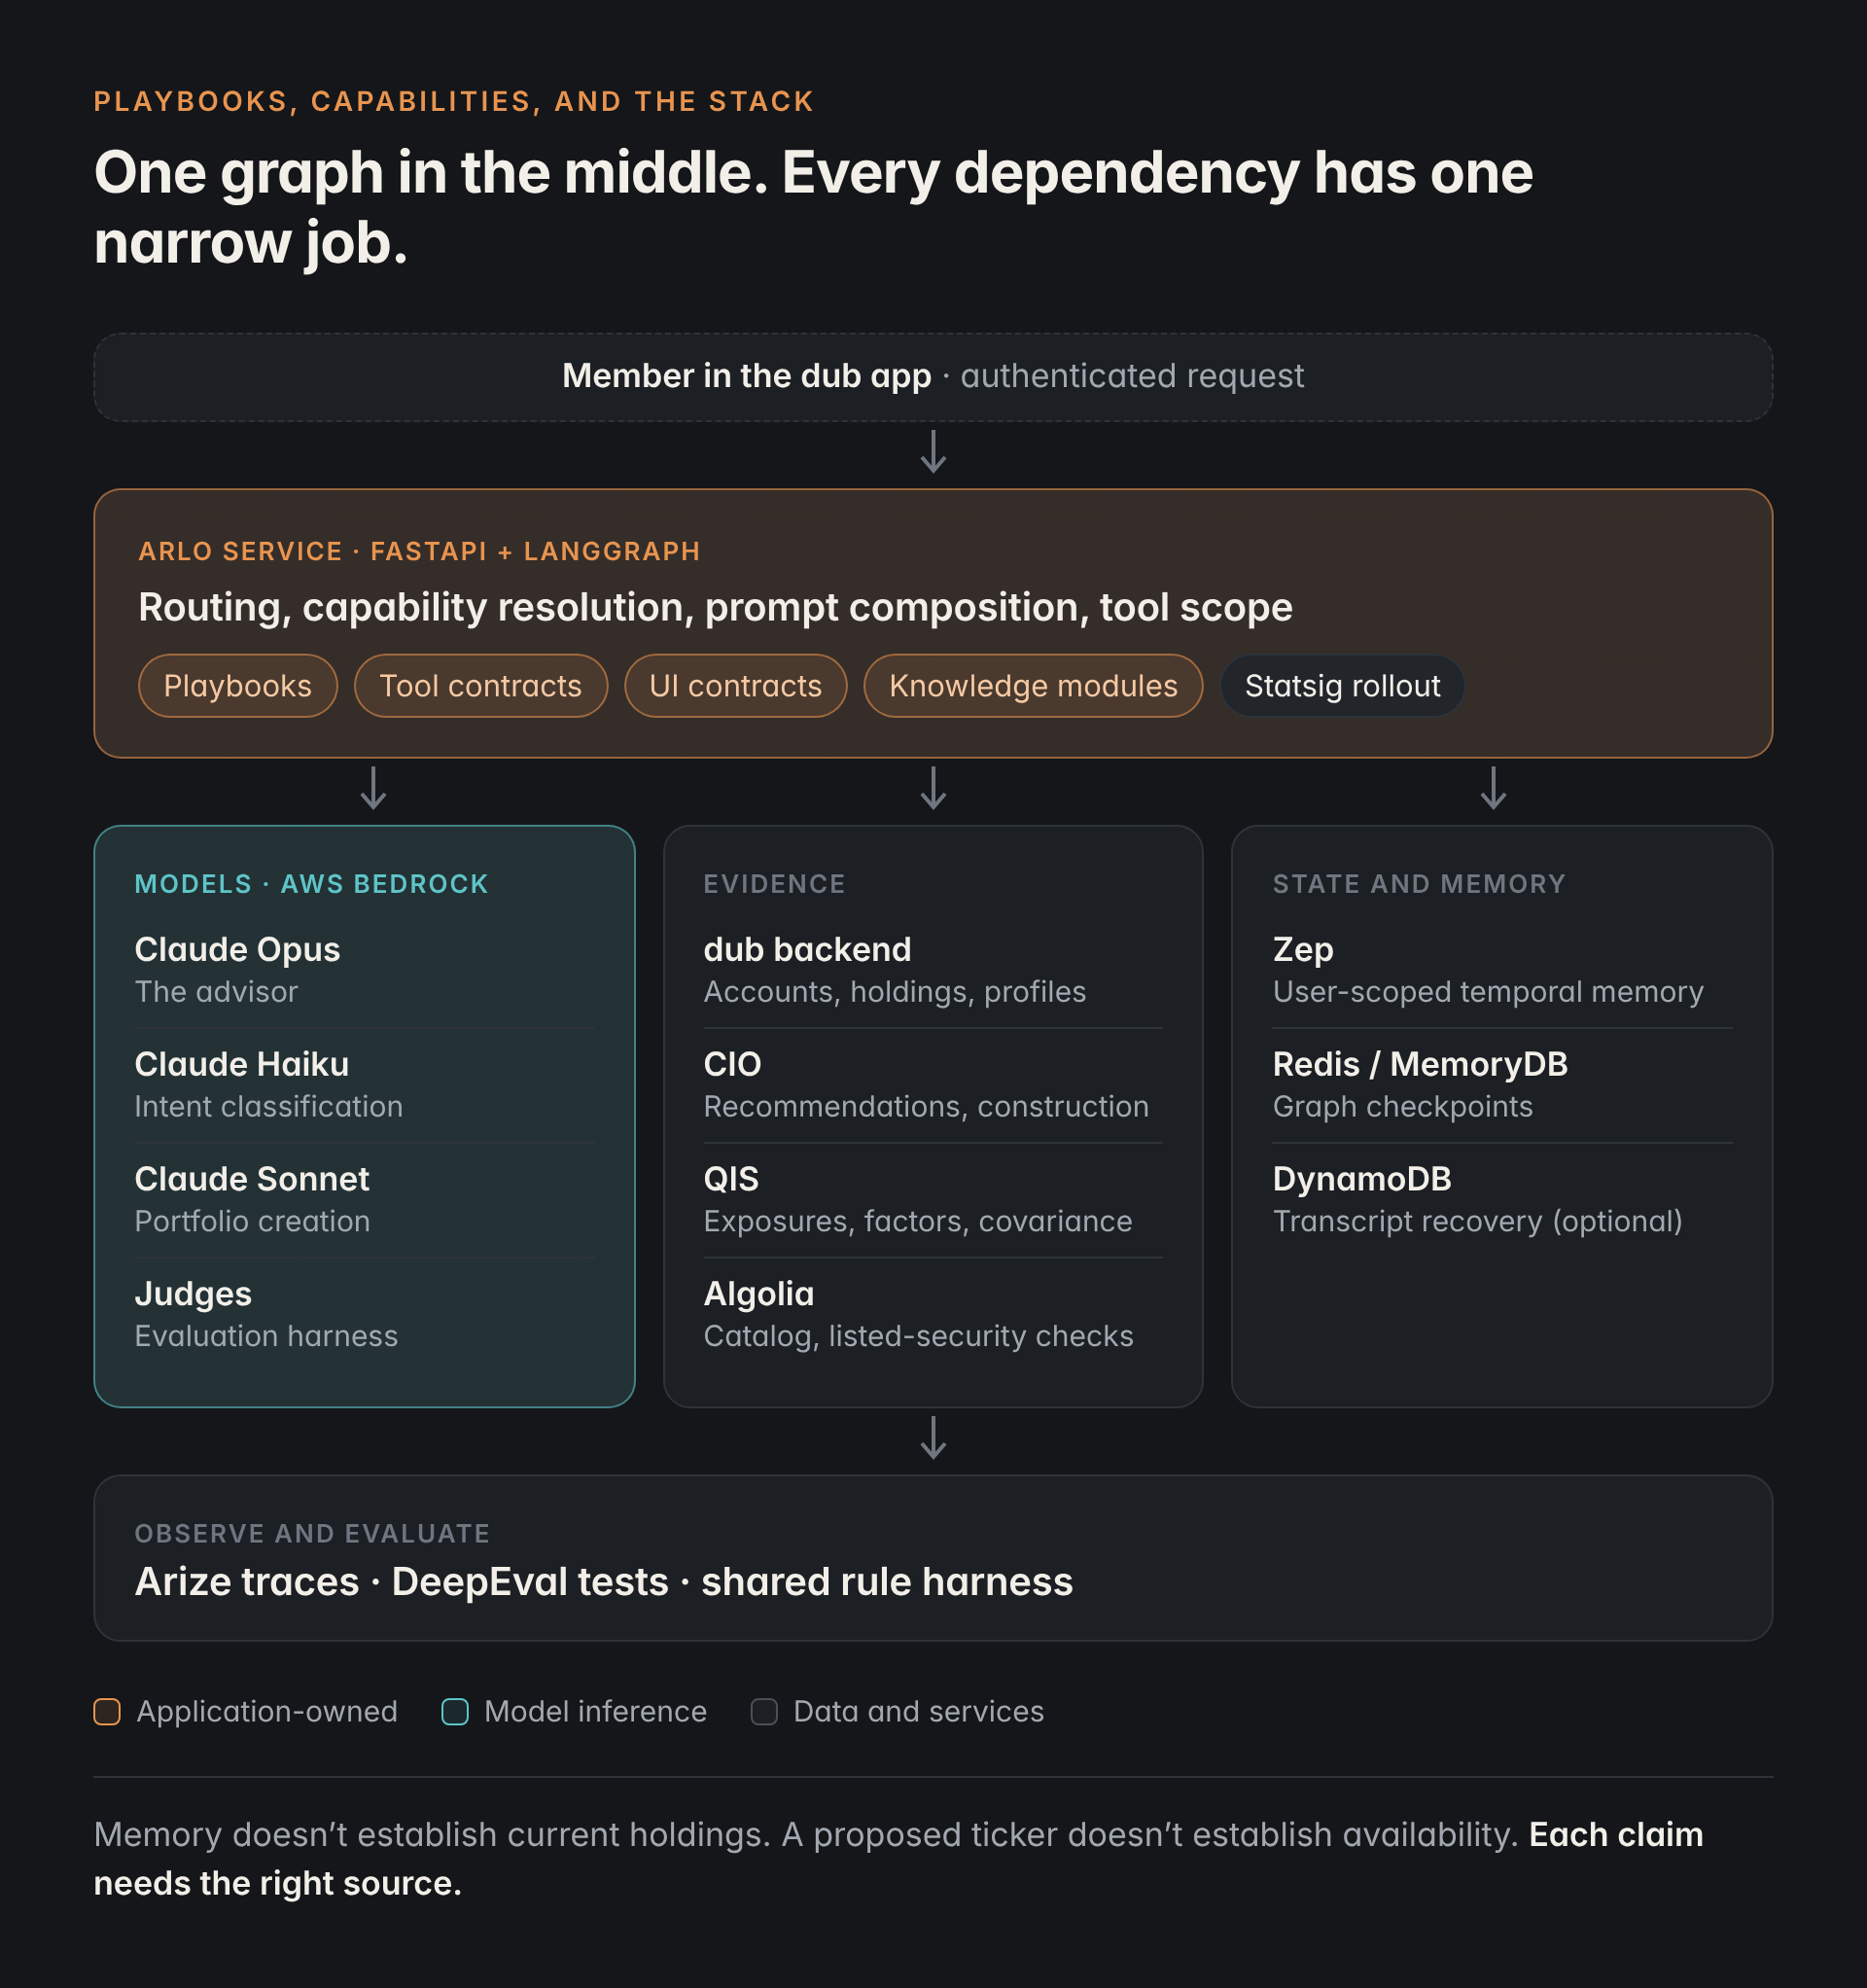
Playbooks describe the job. Capabilities establish whether the runtime can support it. Both are versioned and auditable.
| Abstraction | Responsibility |
|---|---|
| Response mode | Defines the authority of this turn |
| Playbook | Task, evidence, presentation, and boundaries |
| Capability | Logical operation and readiness checks |
| Tool contract | Usage rules and unsupported inferences |
| UI contract | Supported component and approved data source |
| Knowledge module | Selected domain context |
AWS Bedrock: shared inference
Bedrock gives Arlo one surface for model access. Through Converse and the LangChain AWS adapter, messages, streaming, and tool use follow the same integration pattern. We use Claude Opus for the advisor, Haiku for intent classification, and Sonnet for portfolio-creation tasks.
The application owns the model factory, configuration, tool binding, and trace conventions, so new workflows don’t need new provider plumbing. Bedrock serves both the assistant and the evaluation harness’s judges. Prompt caching separates reusable prompt content from member context, and task-specific model choice plus bounded tool loops keep latency and cost in check.
LangChain and LangGraph
LangChain provides chat models, messages, typed tools, and agent middleware, so a capability can expose a schema-defined tool through standard interfaces.
LangGraph provides stateful execution: the model/tool loop, thread checkpoints, and control hooks. Arlo’s graph wrapper binds each request’s tool scope, adds middleware, and emits the agent/LLM/tool trace tree, so state and permitted behavior stay inspectable at every step.
Zep and temporal memory
Zep provides a user-scoped context graph across threads, covering messages, curated business episodes, explicit fact triples, and targeted search. Event timestamps preserve when a fact was valid or superseded.
Arlo retrieves a context block for the authenticated member instead of carrying an ever-growing transcript, applies memory-hygiene rules, and keeps remembered preferences separate from current account data. Zep sits behind internal value objects and stable error codes, so SDK details stay out of the rest of the application.
Arize, DeepEval, and a shared evaluation harness
Arize links traces to datasets, per-dimension evaluations, and human annotation. Reviewers can follow the model/tool sequence, inspect a judge’s rationale, and send disagreements into curation. Online and backfill evaluation reuse the harness’s compiled rules.
DeepEval makes the same framework part of repeatable testing, in two lanes. One wraps the real rule compiler as a metric over golden datasets. The other runs agent-behavior cases with deterministic checks and a graded Bedrock judge, and is currently report-only.
| Supporting layer | Role |
|---|---|
| Python FastAPI and Pydantic | Service boundaries, typed inputs, and structured outputs |
| dub backend | Account facts, holdings, and investor profiles |
| CIO (internal service) | Recommendation pipeline and portfolio construction |
| QIS (internal service) | Quant risk analytics: exposures, factor loadings, and covariance |
| Algolia | Portfolio/catalog discovery and listed-security validation |
| Redis/MemoryDB and optional DynamoDB | Graph checkpoints and durable transcript recovery |
| Statsig | Configuration and cohort rollout |
Each dependency has a narrow role. Memory doesn’t establish current holdings, a proposed ticker doesn’t establish availability, and fluent prose doesn’t establish suitability. Each claim needs the right source.
New capabilities enter through defined prerequisites, tool contracts, UI support, and evaluation coverage.
Compliance: rule packs, judges, and human review
12 evaluation dimensions, separate RIA and broker-dealer rule packs, and human labels as the reference standard.
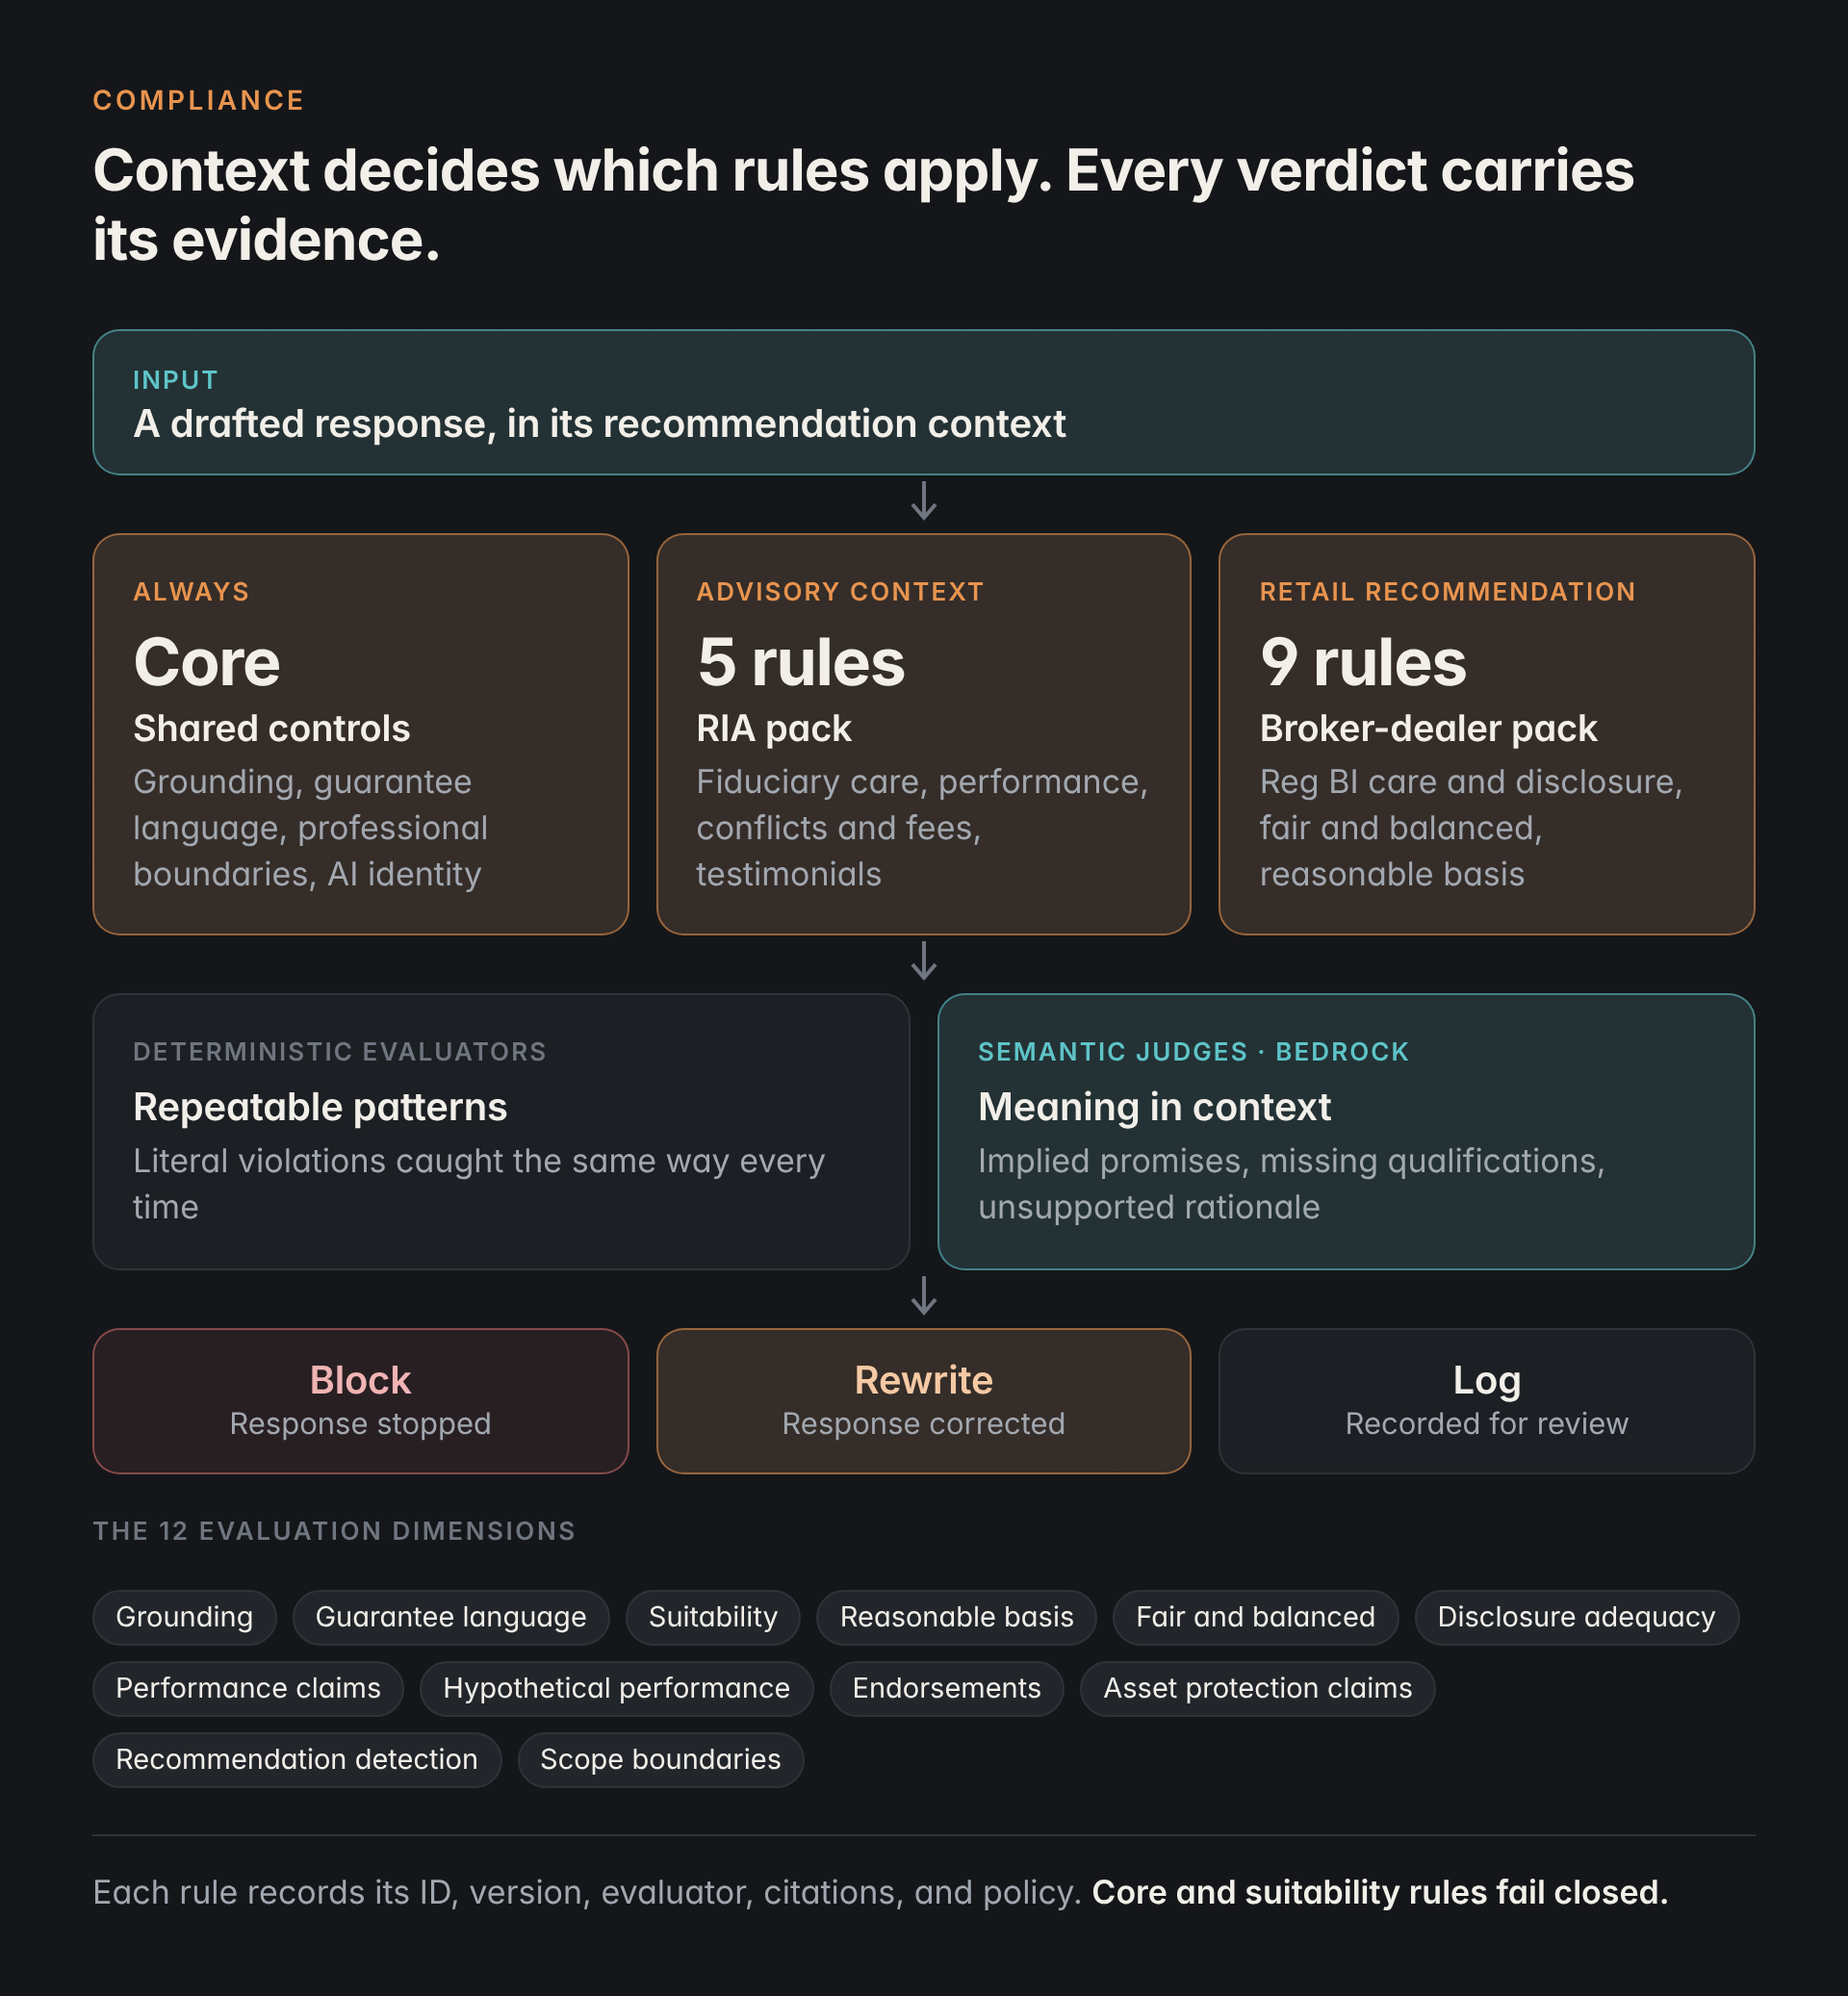
We built the compliance layer around explicit investment obligations. A shared criteria catalog defines 12 evaluation dimensions, and a versioned registry adds 5 RIA rules and 9 broker-dealer rules on top of shared core controls. Each check has a named purpose, a regulatory or firm-policy basis, and evidence a reviewer can inspect.
The registry records each rule’s ID, version, evaluator binding, citations, and policy: block, rewrite, or log. Which rules apply depends on the selected packs and the recommendation context, so the differences between advisory duties, retail recommendations, and communications standards are preserved.
Recommendation detection is a routing classifier, not a separate compliance pass. Five of the 12 dimensions currently have seeded golden datasets.
Deterministic evaluators and semantic judges
Deterministic evaluators catch repeatable patterns and literal violations. Bedrock-hosted judges assess meaning in context: an implied promise, a missing qualification, an unsupported rationale, or a recommendation that doesn’t fit the captured profile. Every rule-linked verdict carries a rationale and evidence, so a failure can become a reproducible example.
Judges treat the evaluated input and output as untrusted data inside randomized delimiters. Outputs are strictly parsed with a bounded retry and explicit technical-failure flags. Core and suitability rules fail closed, and other rules declare their own failure policy. A judge outage stays visible in the record.
Human review anchors the evaluation loop
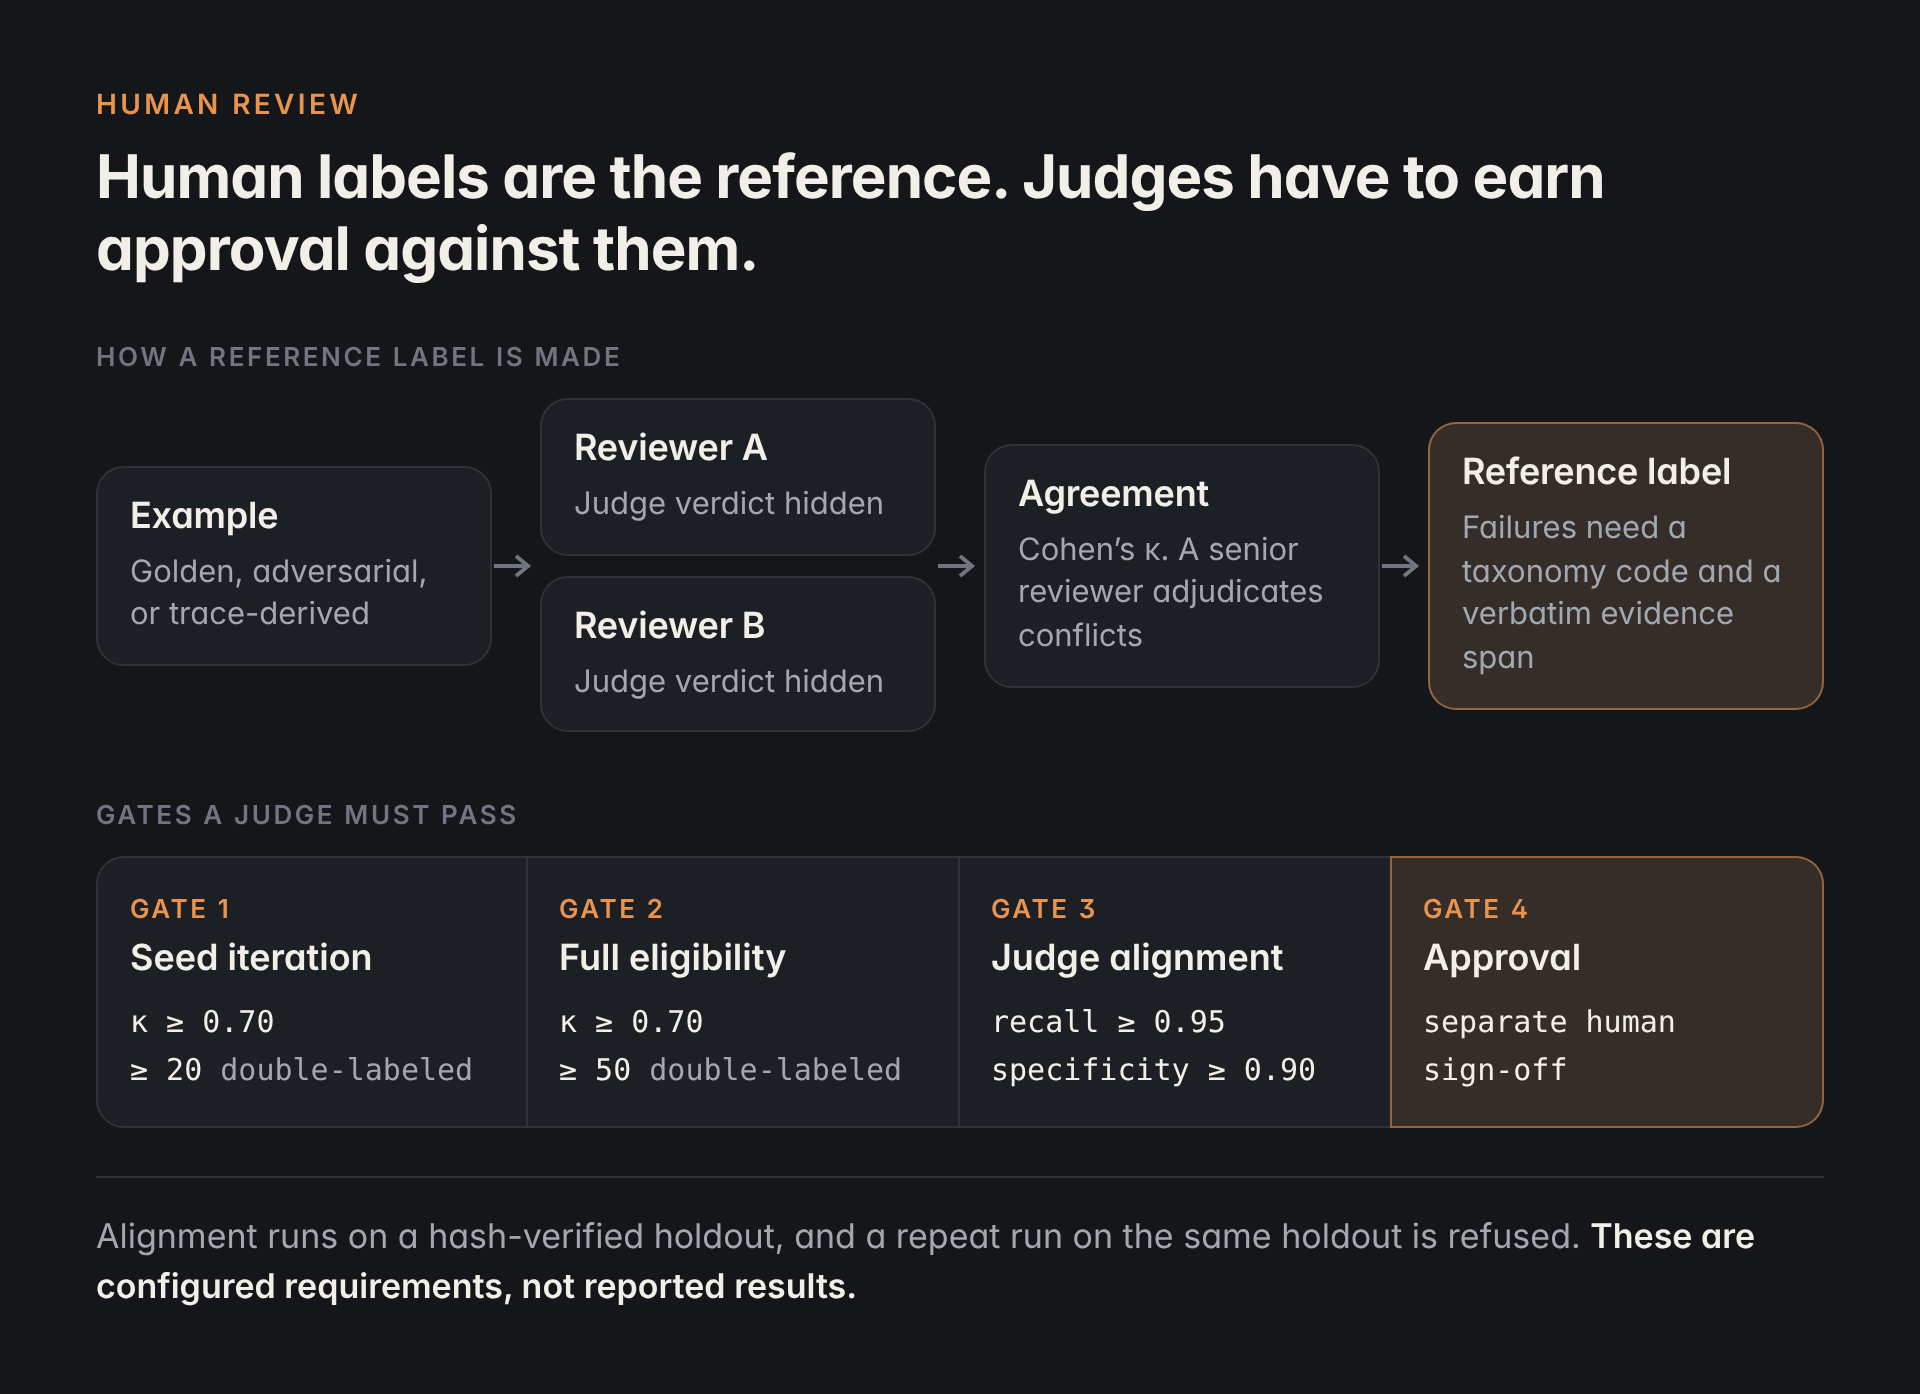
At least two independent reviewers label each reference example, working from a versioned guideline. A failure label requires a taxonomy code and a verbatim evidence span. Agreement is measured with Cohen’s kappa, and a senior reviewer adjudicates disagreements, which sometimes expose ambiguity in the guideline itself. In Arize, reviewers can’t see the judge’s verdict while labeling, so a model’s decision can’t become its own validation.
Each judge must pass explicit approval gates. These are configured process requirements, not reported results.
The result is a traceable loop: a reviewer identifies a failure with evidence, the expected behavior is resolved, and that decision becomes criteria, test cases, and a versioned change.
Personalized recommendations
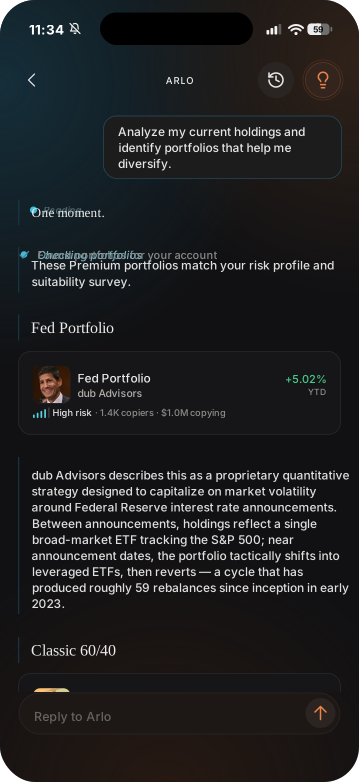
Personalization is a backend evidence pipeline with a constrained conversational layer.
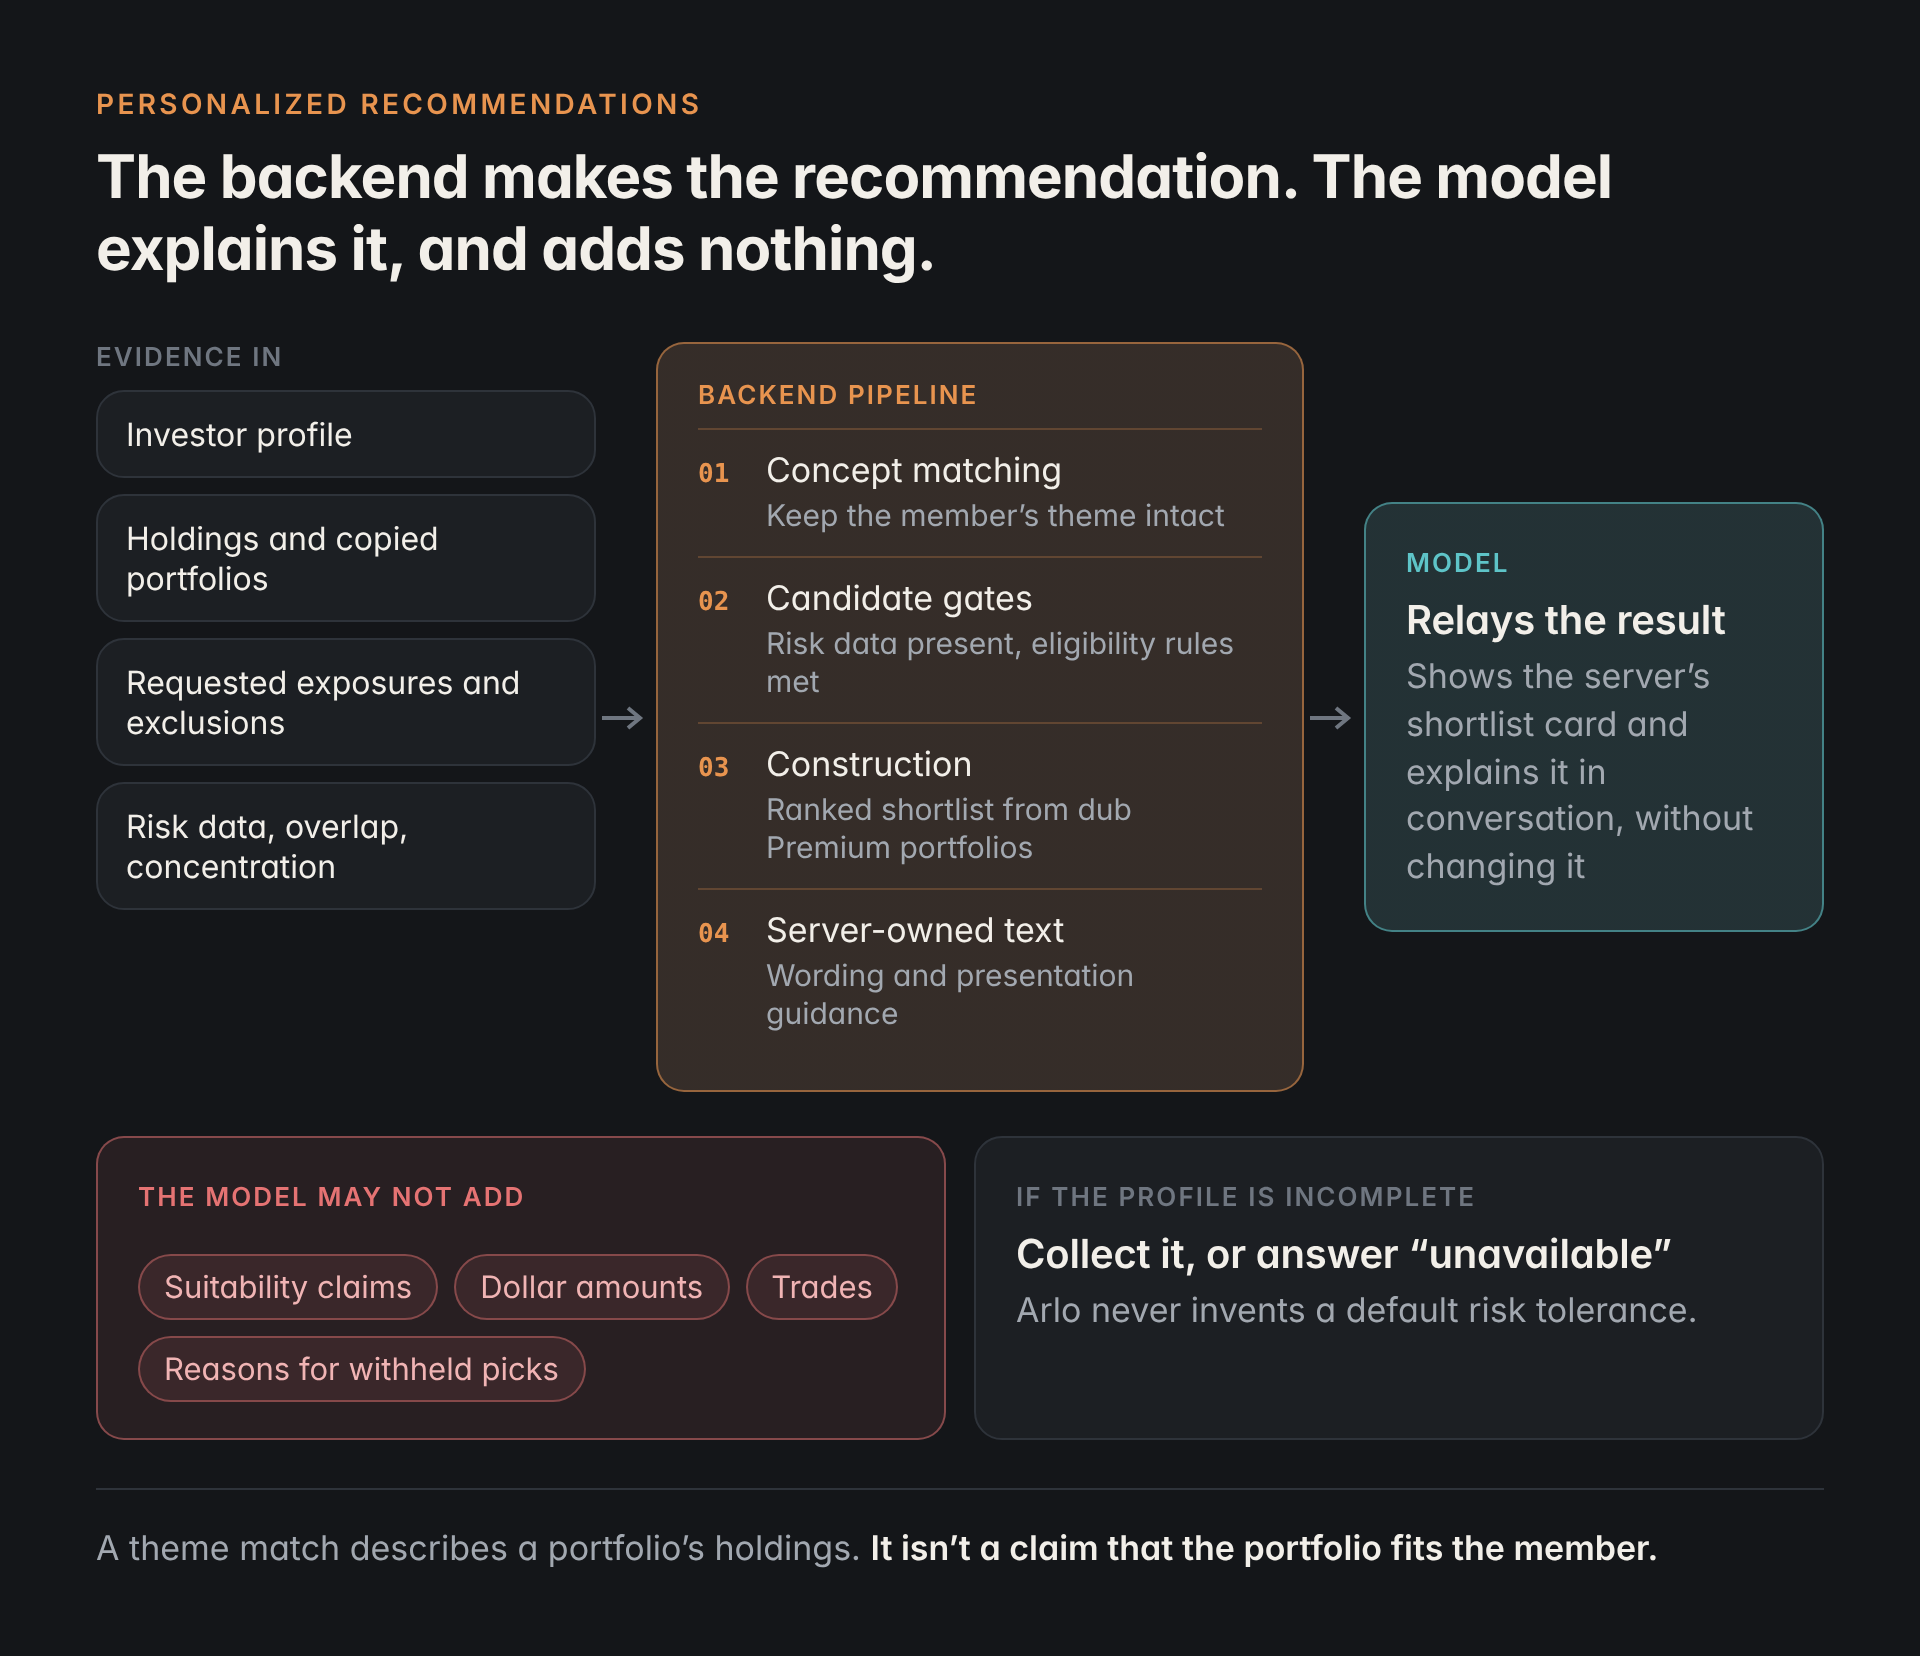
The model translates the member’s request into a typed route and constraints. The backend owns the recommendation pipeline, drawing on the investor profile, account data, copied portfolios, holdings, requested exposures, exclusions, portfolio risk data, and account-relative measures like overlap and concentration.
Theme requests move through concept matching, candidate gates, and construction. Other routes handle account-oriented requests, explicit screens, historical-performance questions, and creator discovery. Recommendations currently draw from dub’s Premium Portfolio universe, and the response has to say so.
Matching a theme and being suitable are different claims. An exposure match says something about a portfolio’s holdings, not about whether it fits the member. A lower-beta candidate doesn’t mean adding it lowers total account risk; that claim needs a tool that scores the combined account after the addition.
The recommendation tool returns server-owned text and presentation guidance, and its contract requires the model to relay it without adding suitability claims, dollar amounts, trades, or reasons for withheld candidates. If the investor profile is incomplete, Arlo collects it or returns an explicit “unavailable” outcome. It never invents a default risk tolerance.
Weak matches are handled separately. Where supported, the closest match can appear as informational context, bounded so it can’t quietly become a recommended pick.
Measuring risk and suitability
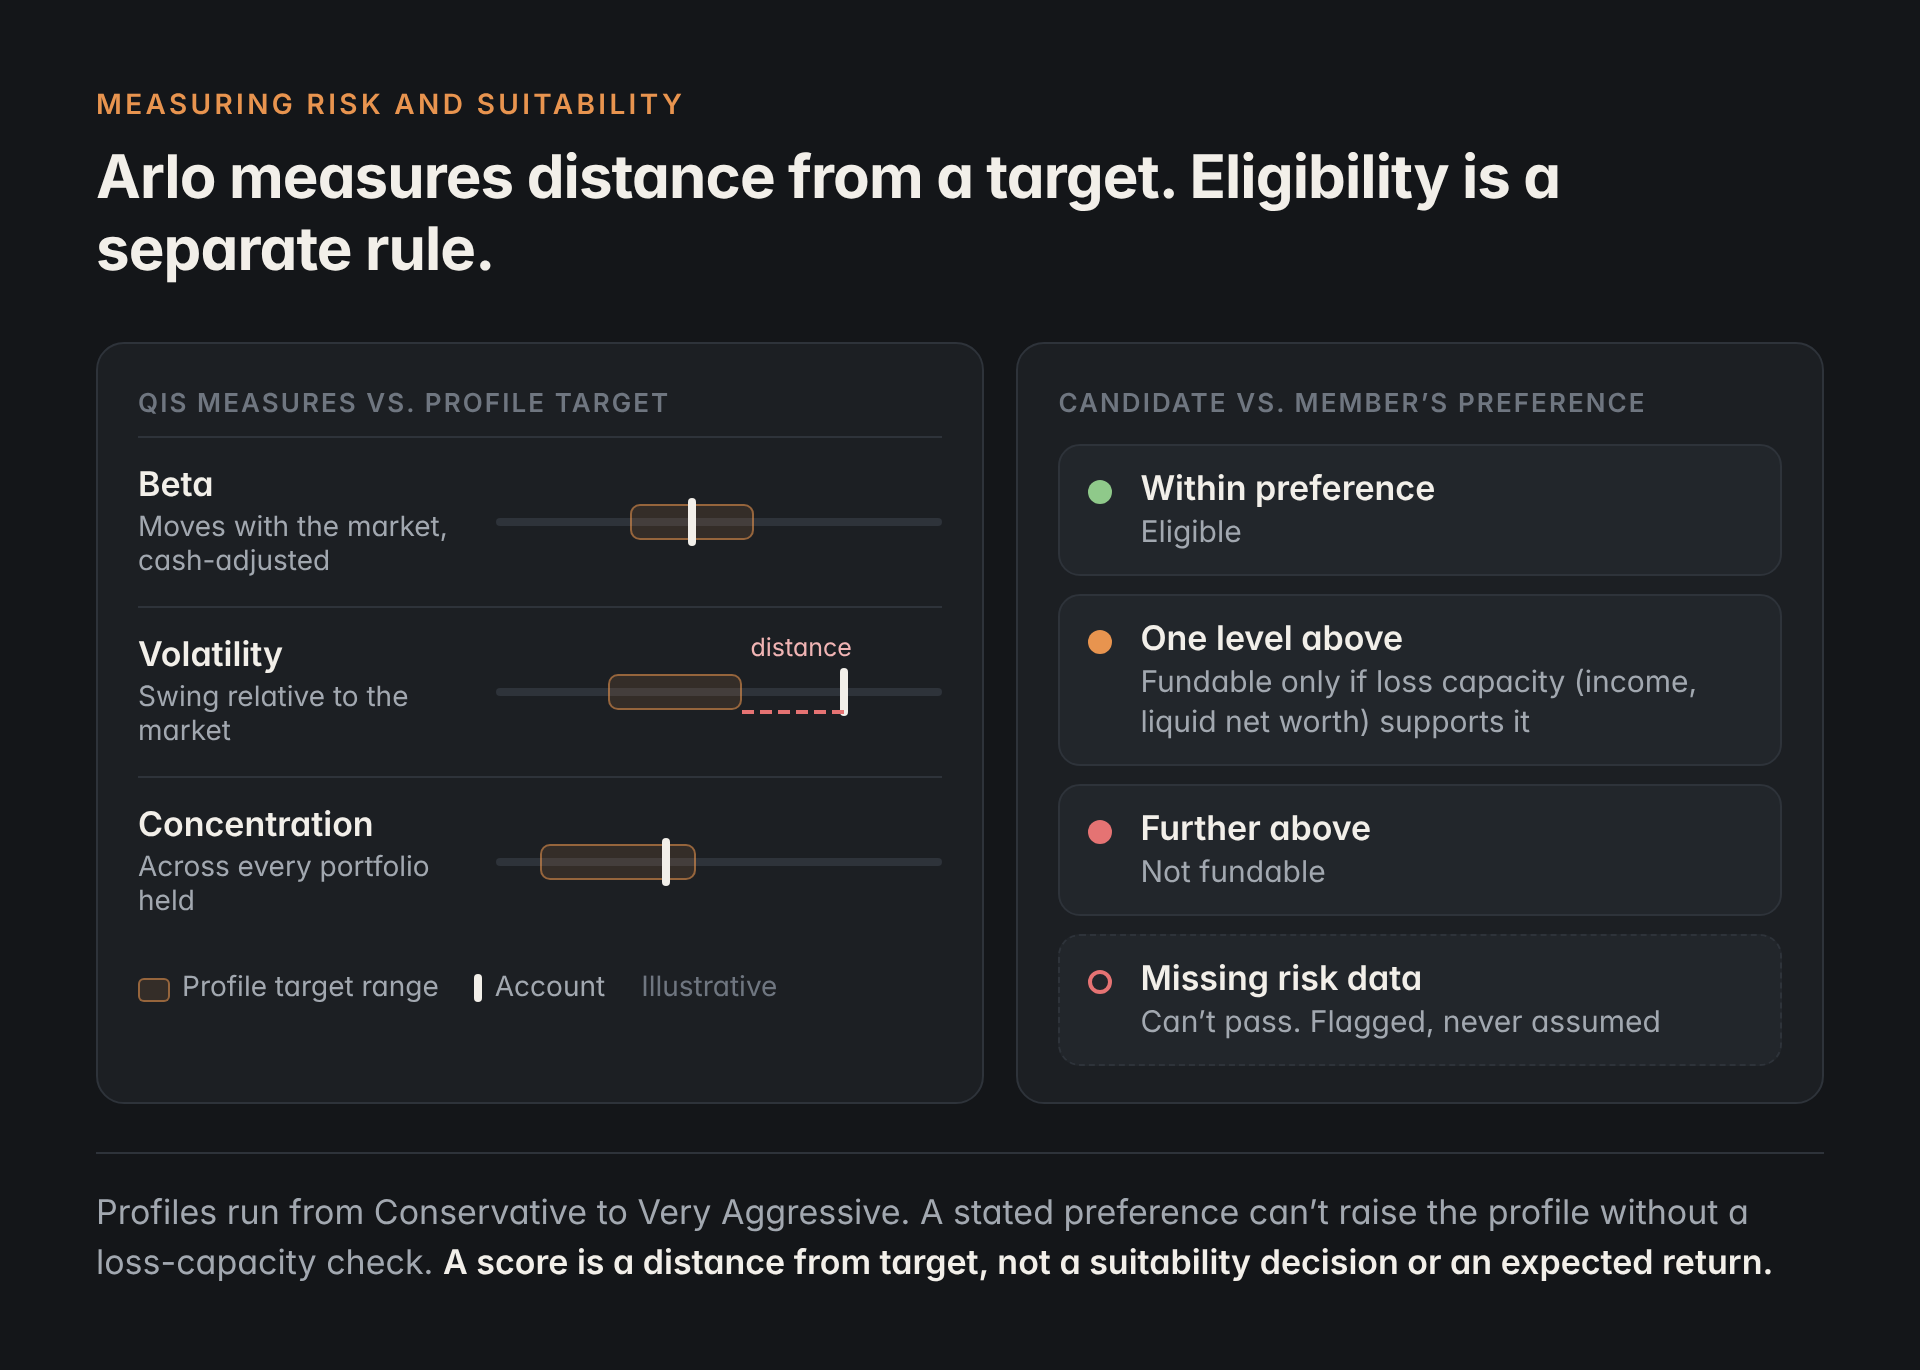
QIS, our internal quant service, breaks every holding down into its underlying exposures and estimates how much risk an account carries. Arlo works from three measures:
- Beta: how much the account tends to move with the market, adjusted for cash.
- Volatility: how much the account’s value tends to swing relative to the market. It’s a risk measure, not a return forecast.
- Concentration: how much the account depends on a few names or sectors, measured across every portfolio it holds. Owning several portfolios with the same stocks can still leave an account concentrated.
Profile targets. Each risk profile, from Conservative to Very Aggressive, sets target ranges for these measures. The profile comes from the member’s risk level and survey answers, which also capture a separate risk preference. Without a loss-capacity check, a stated preference can’t raise the profile on its own.
Scoring. Arlo scores how far an account or candidate sits outside its target ranges. That score is a distance from target, not a suitability decision or an expected return, and missing data is flagged rather than treated as a pass.
Eligibility. Candidates are labeled within, one level above, or further above the member’s preference. A one-level stretch is fundable only when the member’s loss capacity, based on income and liquid net worth, supports it. Anything further above isn’t fundable, and a candidate without the required risk data can’t pass.
Account fit. Arlo can check how adding a candidate would change the account’s concentration and beta. These are directional signals, not claims about total risk or performance.
Construction. Where a route builds a recommendation, a constrained optimizer works within position limits, concentration, beta, and stress-loss bounds, and independent checks verify the result. If a solve needs to relax, only designated calibration settings can loosen. Member instructions and hard limits never do.
Measured risk, profile targets, and eligibility rules are distinct layers. Calibration remains explicit.
Portfolio creation from investment ideas
An investment thesis can become a concrete portfolio draft the member can inspect, refine, and edit.
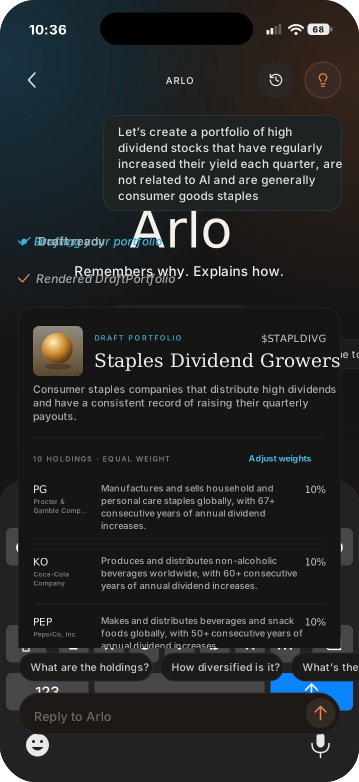
An idea might start as a theme, a conviction about a business, an exposure to explore, or something to avoid. Arlo turns that into a structured creation workflow. Asking Arlo to build your own portfolio follows a different path from asking it to recommend an existing dub portfolio.
"Help me explore the infrastructure behind AI, while excluding consumer applications."
| Member input | Creation behavior |
|---|---|
| A theme or investment idea | Generate candidates tied to that concept |
| An exclusion | Carry it into candidate selection and validation |
| A bearish thesis | Where supported, translate it into an alternative concept and exclude the original bearish exposure |
| A revision to an existing draft | Pass the draft identity and current holdings through the validation workflow again |
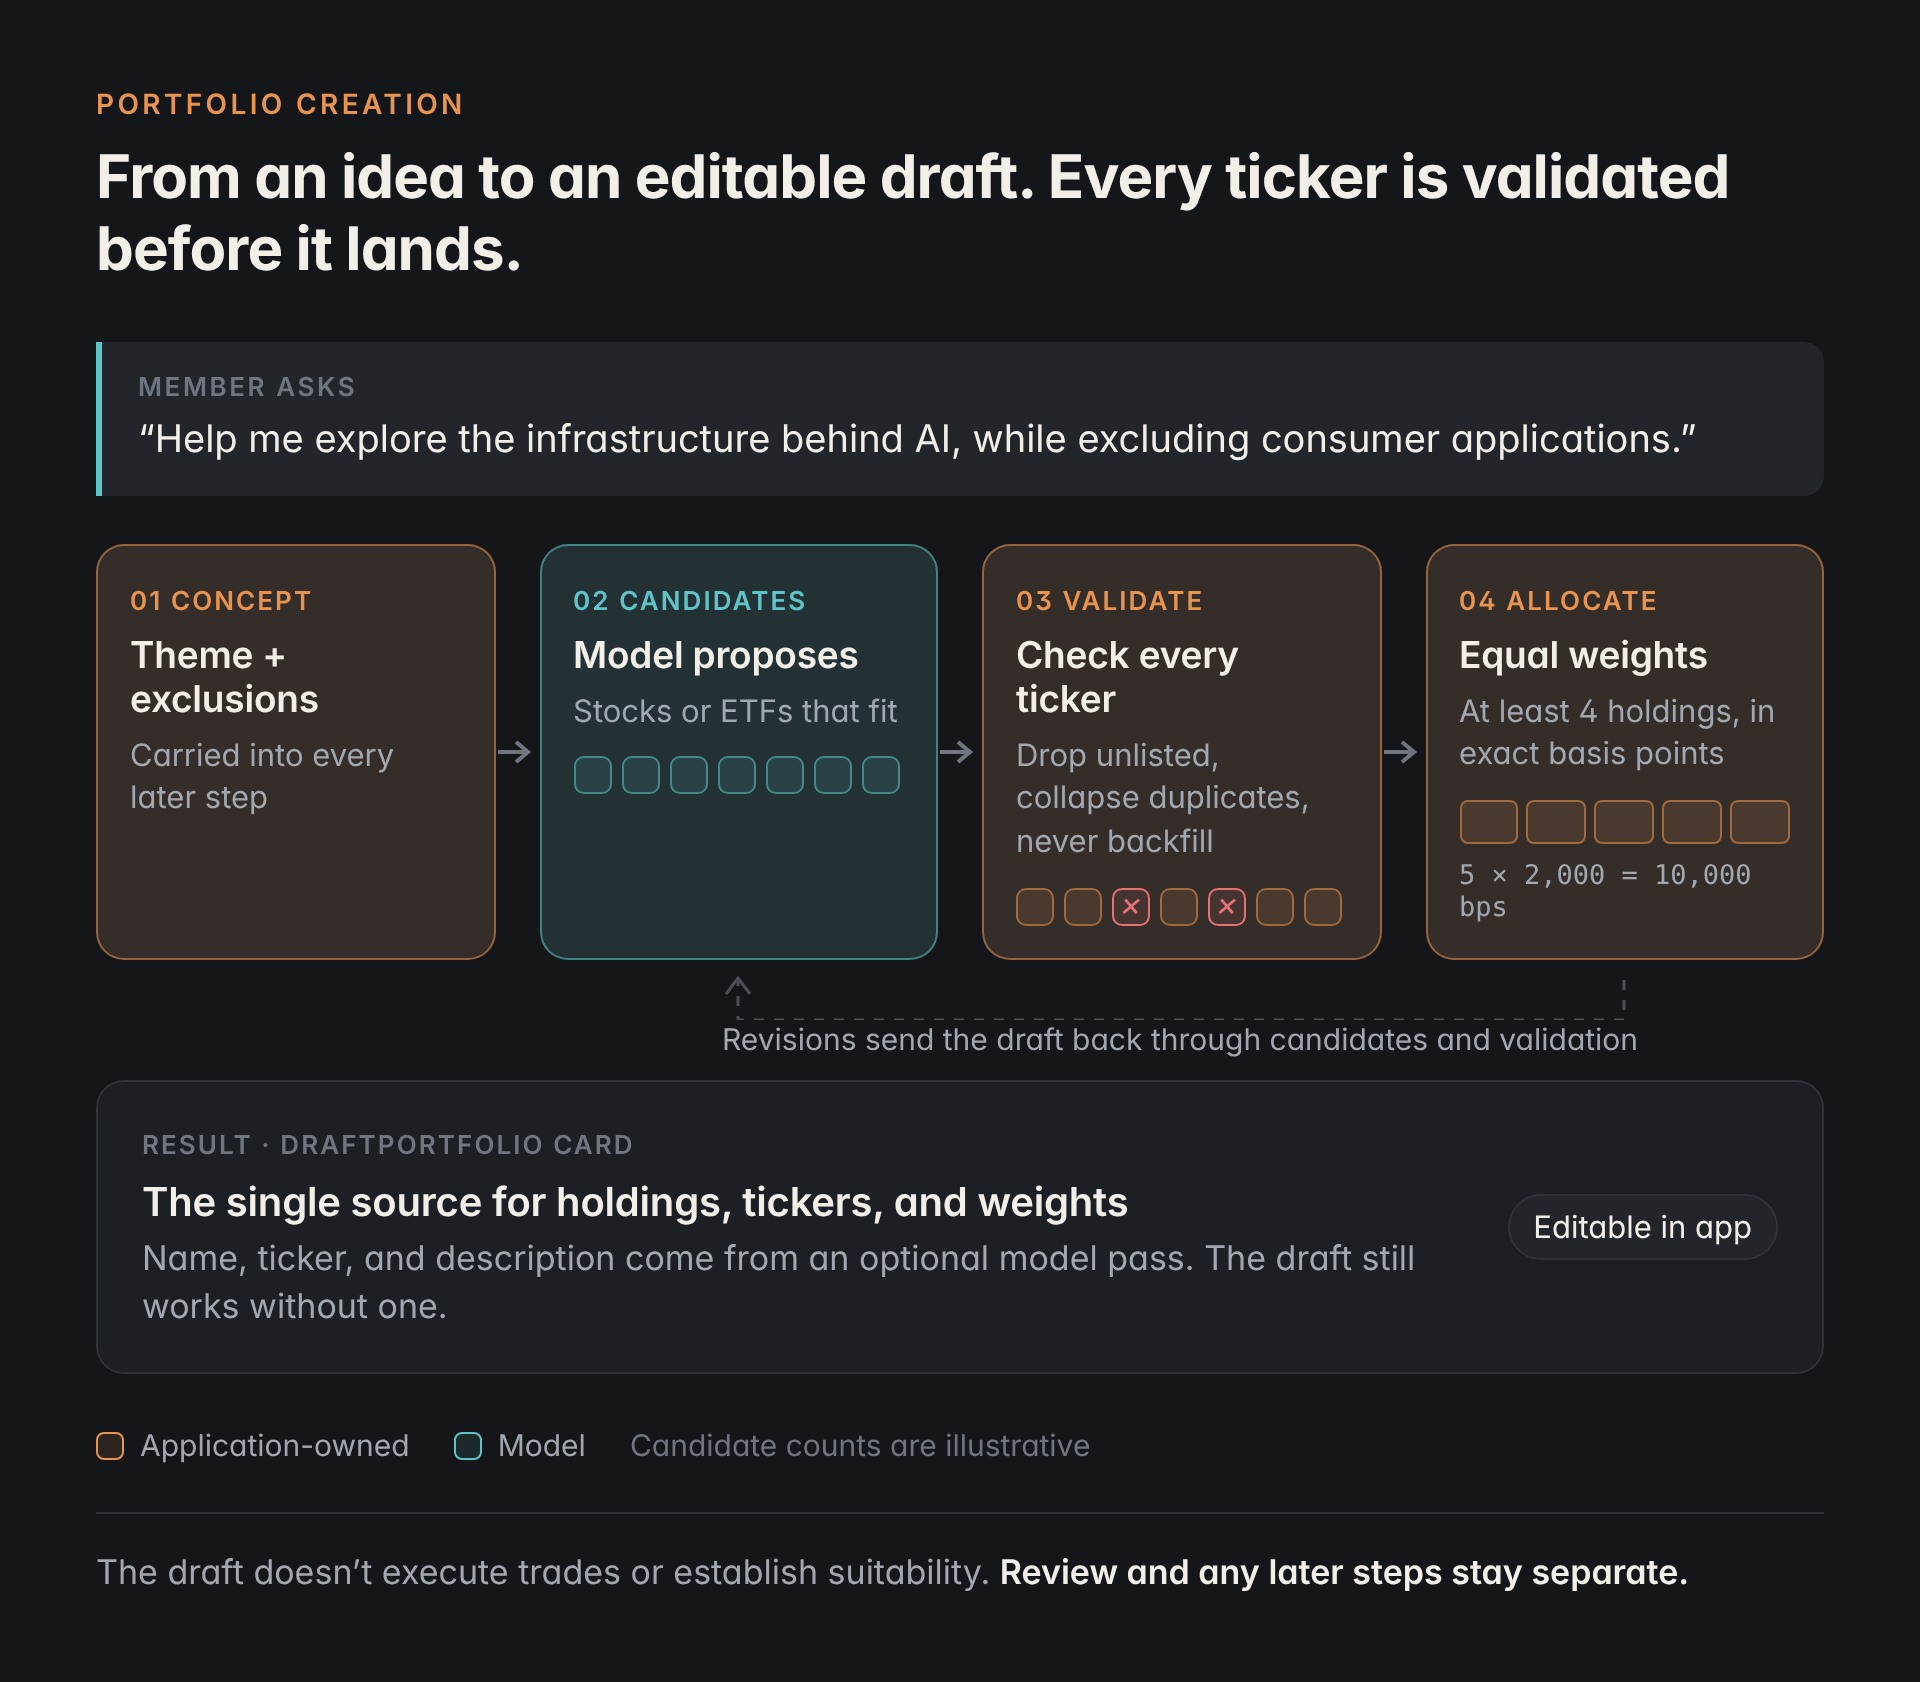
A specialized model proposes stocks or ETFs that fit the concept and exclusions. The service then checks every candidate against Algolia’s Stocks index. Unlisted candidates are dropped, duplicate tickers collapse, and the service never invents replacements to fill gaps. The advisor path requires at least four validated holdings.
Validated holdings get deterministic equal starting weights, stored as exact basis points summing to 10,000. A separate, time-bounded model pass suggests a name, ticker, and description, and the draft still works if naming is unavailable.
Creation is iterative. A revision carries the draft’s identity and current holdings back through the picker and validator. For supported bearish views, a separate step proposes a different investable theme and rejects any alternative that simply repeats the bearish or excluded concept.
The draft doesn’t execute trades or establish suitability. Review and any later product flows remain separate.
Model-proposed candidates. Validated securities. Deterministic starting allocations. An editable result.
Market intelligence grounded in the user's question
Explain the development, show the sources, and connect it to supported investment context.
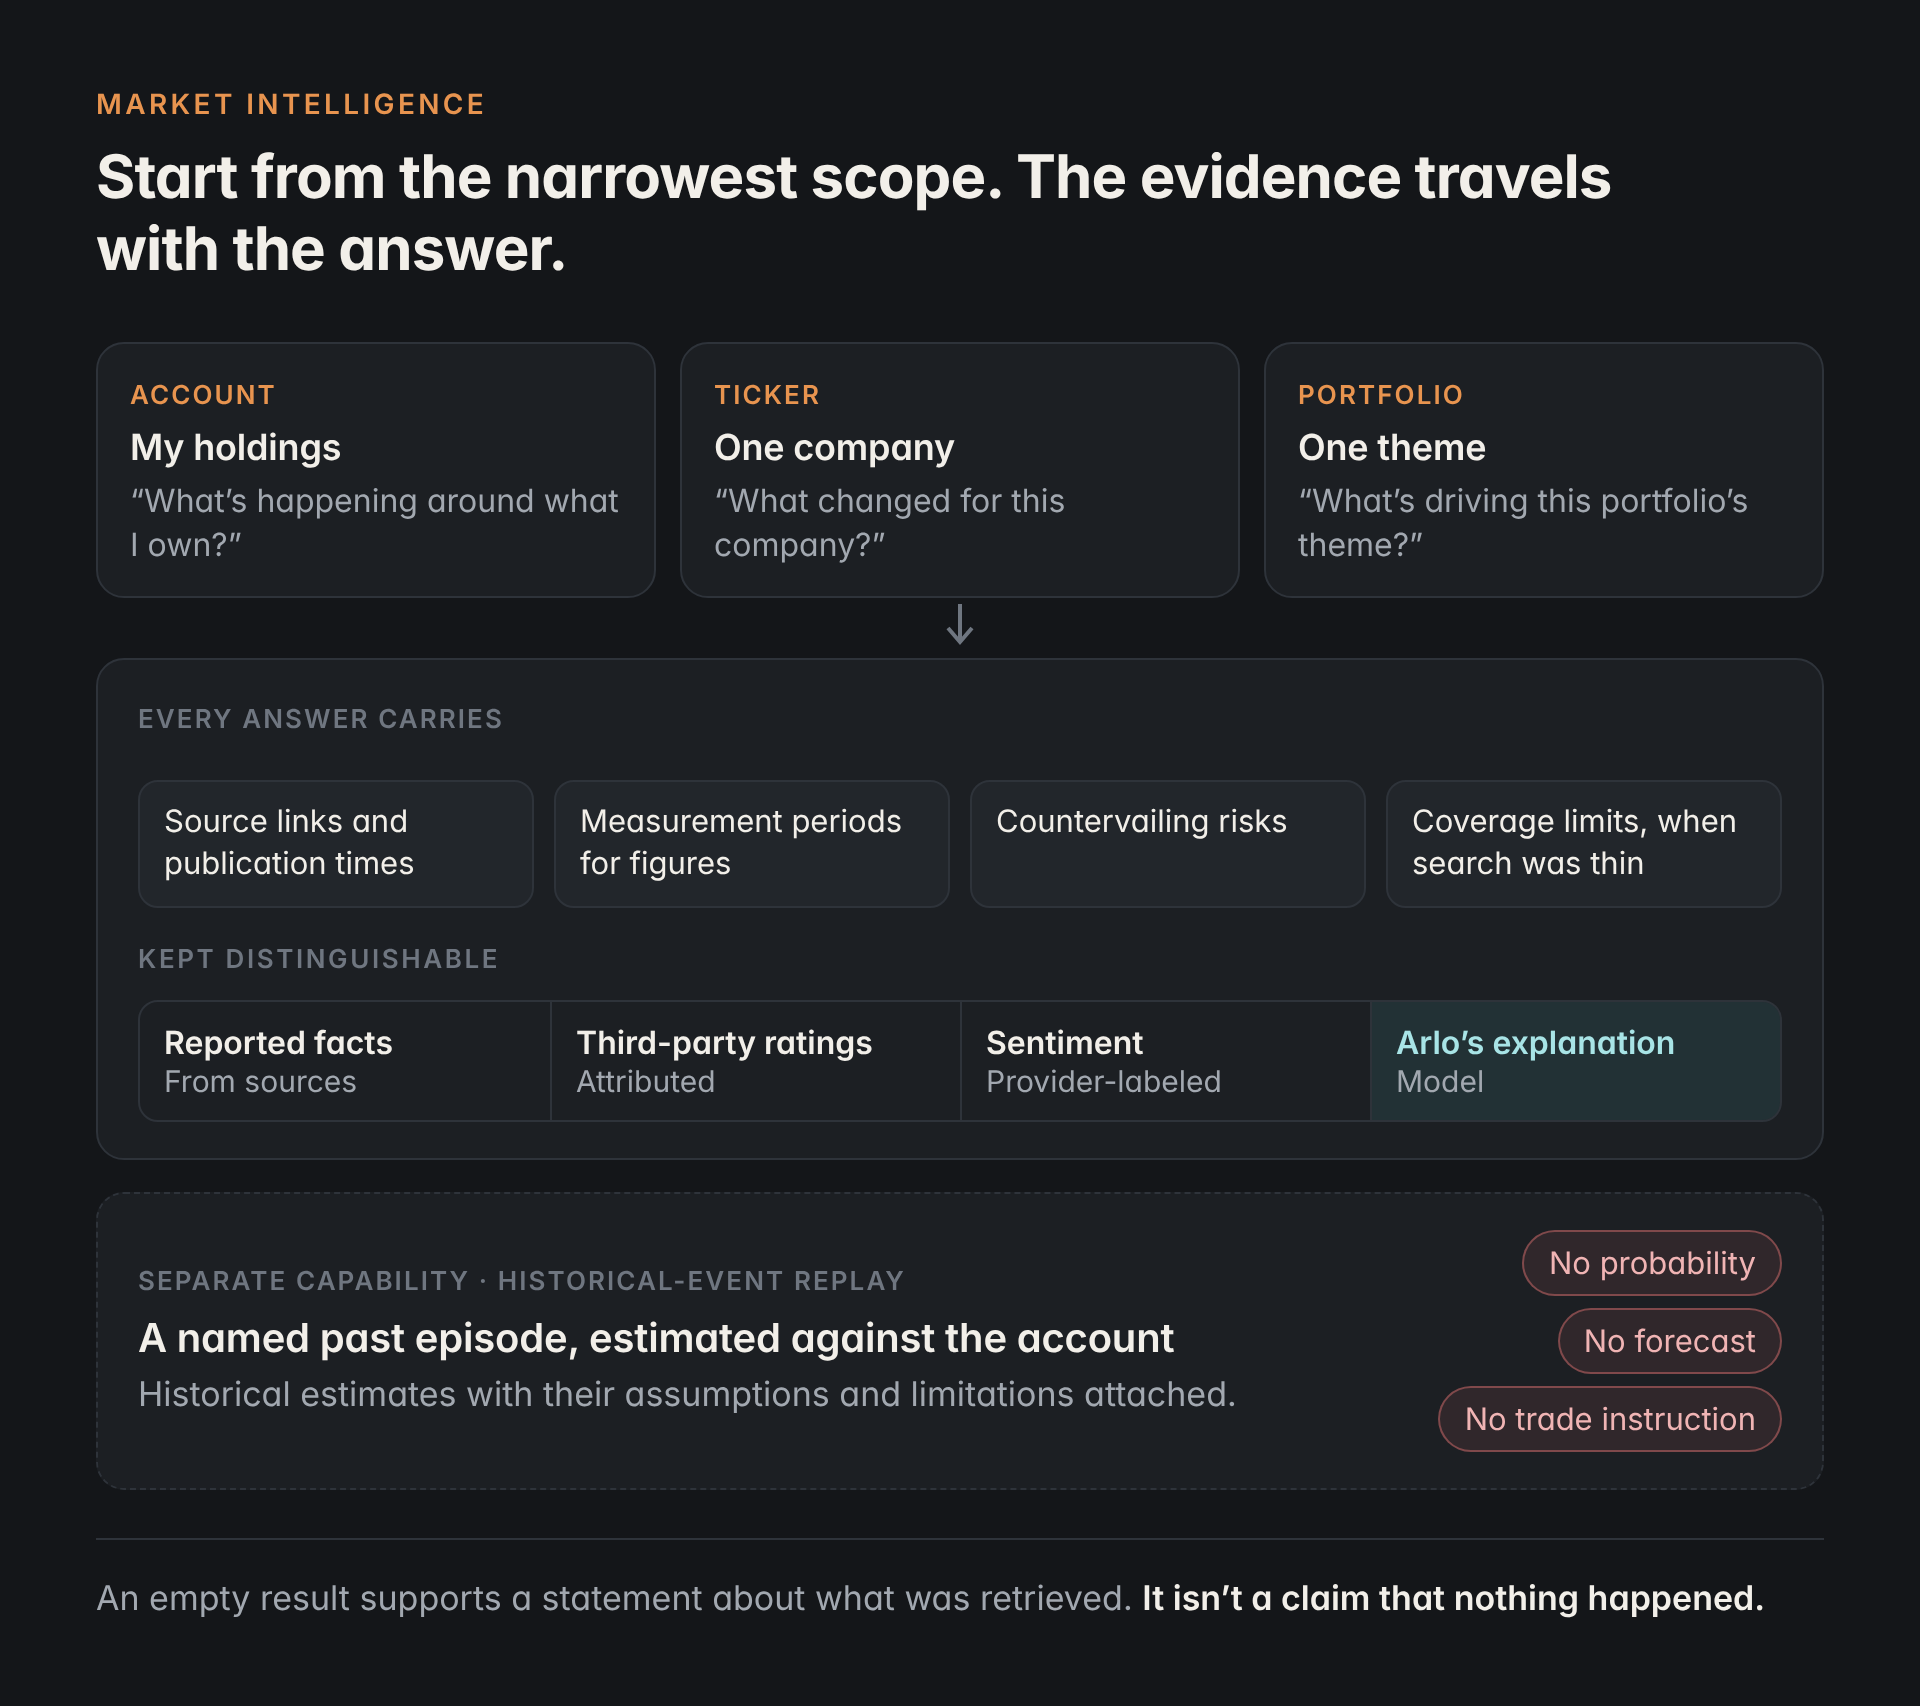
A headline is more useful when a member can see what it means for a security, a portfolio, or their own account. Arlo’s market-news playbook picks the narrowest scope that fits the question.
| Investment question | Evidence path |
|---|---|
| What is happening around my holdings? | Scope relevant news to the current account |
| What changed for this company? | Resolve the ticker and retrieve security-specific news and supported research |
| What is driving this portfolio’s theme? | Use the named portfolio’s context and relevant sources |
| How would this past market episode relate to my account? | Use the separate historical-event replay workflow |
The retrieval contract carries article links and publication metadata into the answer, and the workflow requires source attribution, measurement periods for market figures, and countervailing risks. If coverage is thin or the search window was widened, the answer says so. An empty result supports a statement about what was retrieved, not a claim that nothing happened.
Stock research adds security details, current quotes with as-of context, and supported research cards. Arlo keeps reported facts, third-party ratings, provider-labeled sentiment, and its own explanation distinguishable. A sentiment label alone doesn’t say what an investment will do next.
Historical-event replay is a separate capability. A named catalog episode can be replayed against the account to produce historical estimates for that episode, with its assumptions and limitations carried forward. It does not supply a probability, a best- or worst-case forecast, or a trade instruction.
Market intelligence should make the evidence easier to inspect and the next question easier to ask.
Security, privacy, and action controls
Security starts at the request boundary and continues through tool execution and tracing.
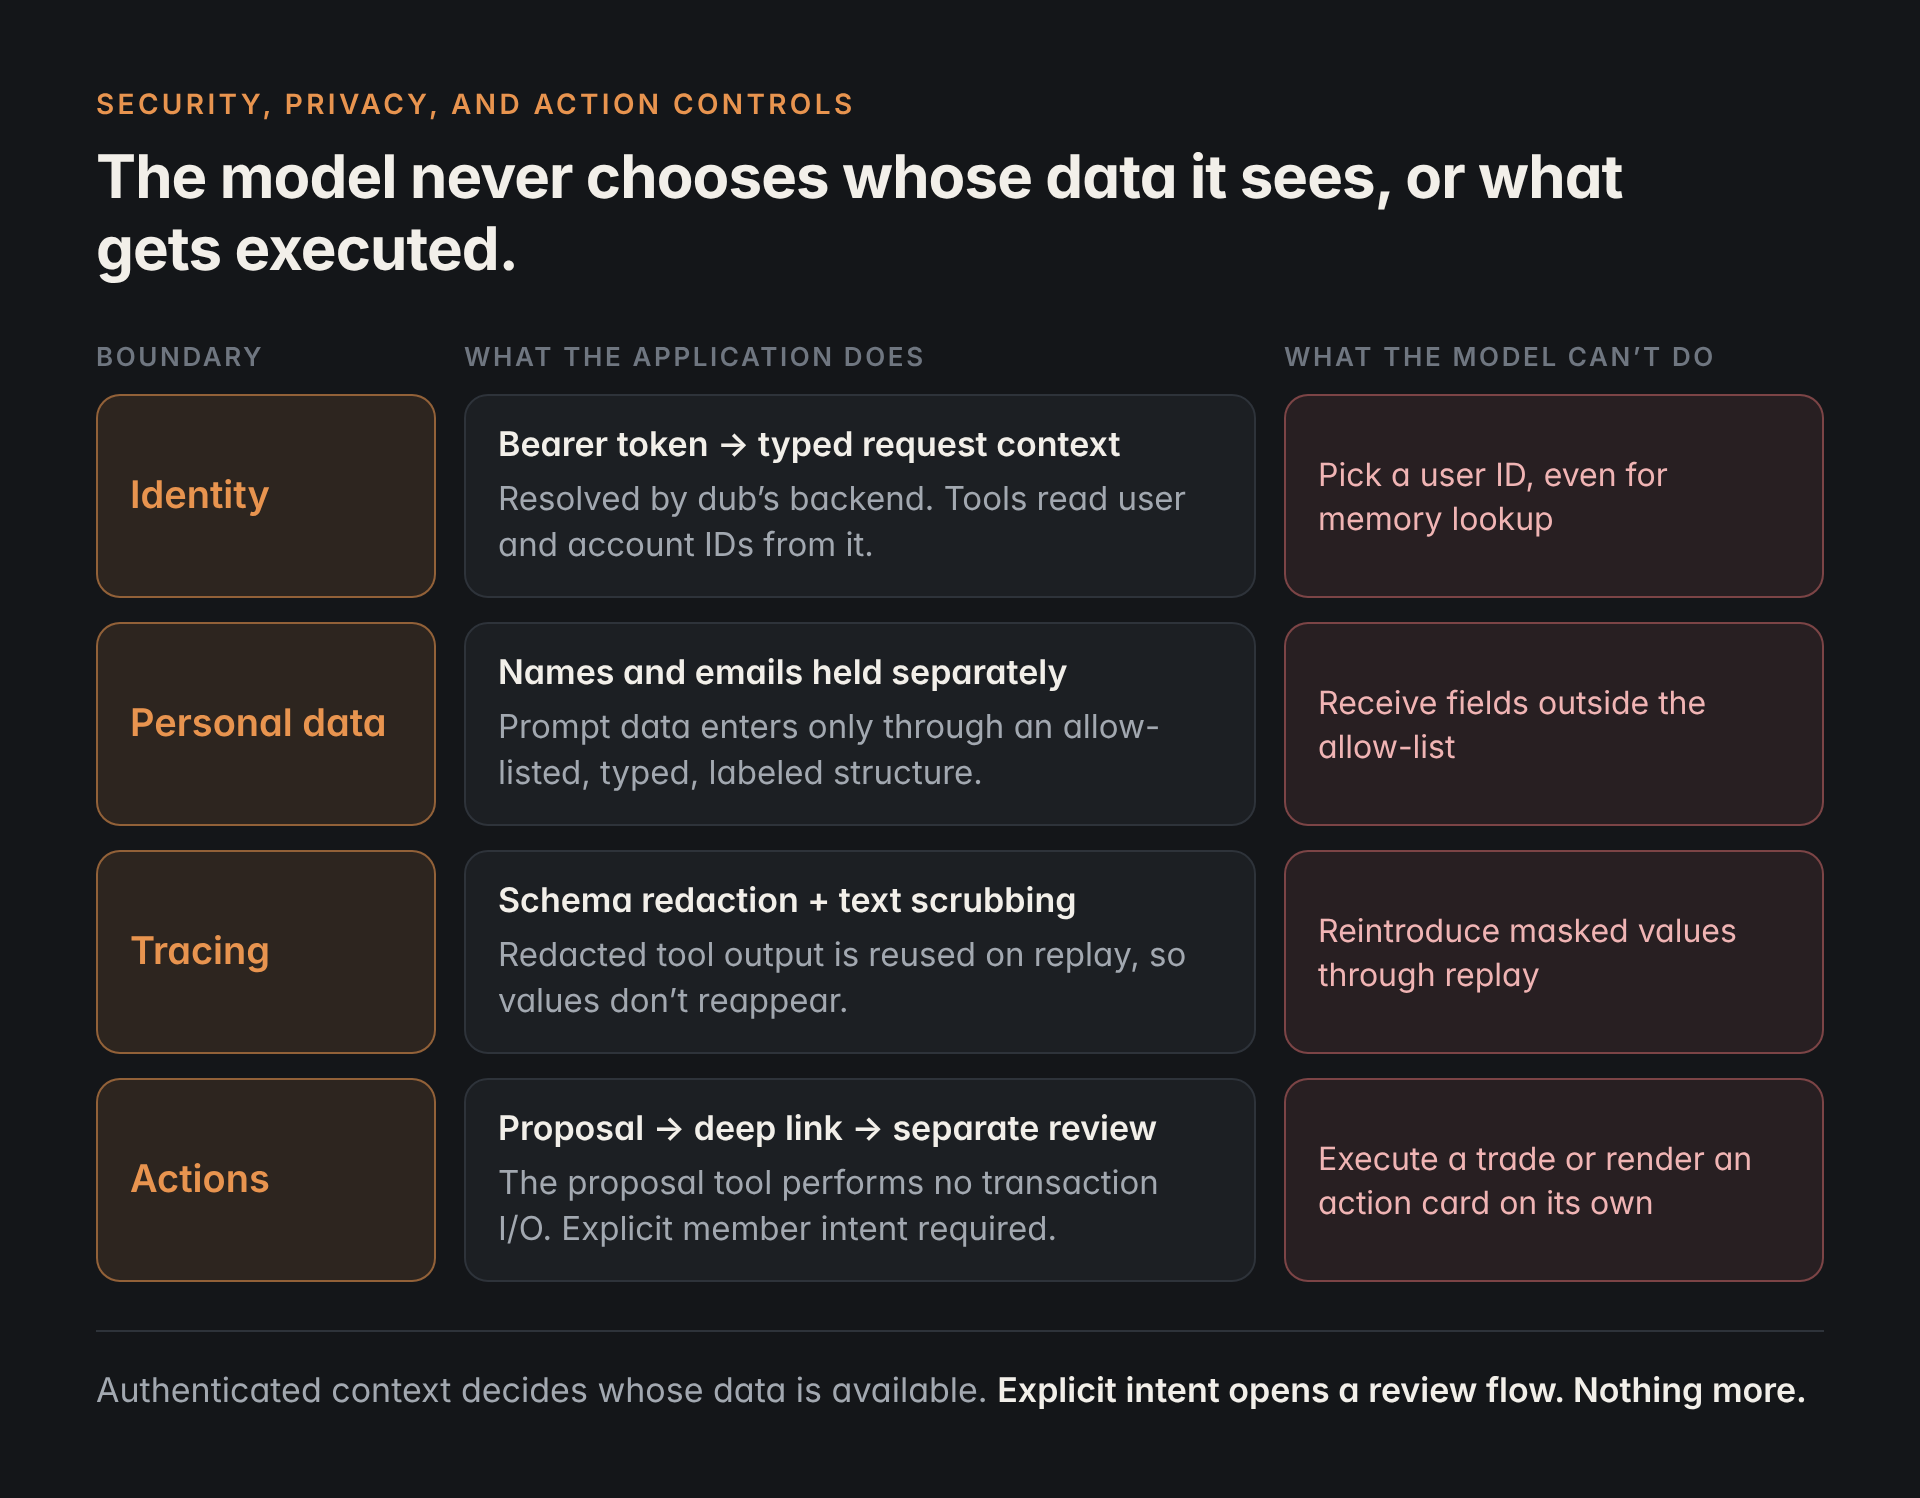
Identity. Each request resolves a bearer token through dub’s backend and builds a typed context with the authenticated user and account IDs. Identity-sensitive tools read from that context, not from the model. Memory retrieval, for example, takes the user ID from the authenticated request and never accepts one the model chooses.
Personal data. Names and email addresses live in a separate request-state profile, outside the identity context that’s safe to log or pass to MCP. Request-scoped data enters the prompt only through an allow-listed, type-checked structure with bounded strings and an explicit data label.
Tracing. Schema-based redaction masks fields marked sensitive, and name, email, and phone scrubbing covers free text. Redacted tool output is carried into trace metadata so sensitive values aren’t reintroduced when a conversation is replayed. This protects telemetry within its configured coverage. Authorized model inputs and tool execution can still require real values.
Actions. Actions require explicit member intent. The proposal tool performs no transaction I/O; it returns a confirmation deep link into a separate review flow. The generic UI renderer can’t create an action card on its own. Permissions, tool exposure, and transaction boundaries stay with the application.
Authenticated context determines whose data is available. Explicit intent opens a review flow.
Tracing and the improvement loop
Tracing connects runtime behavior to evaluation, human review, and engineering changes.
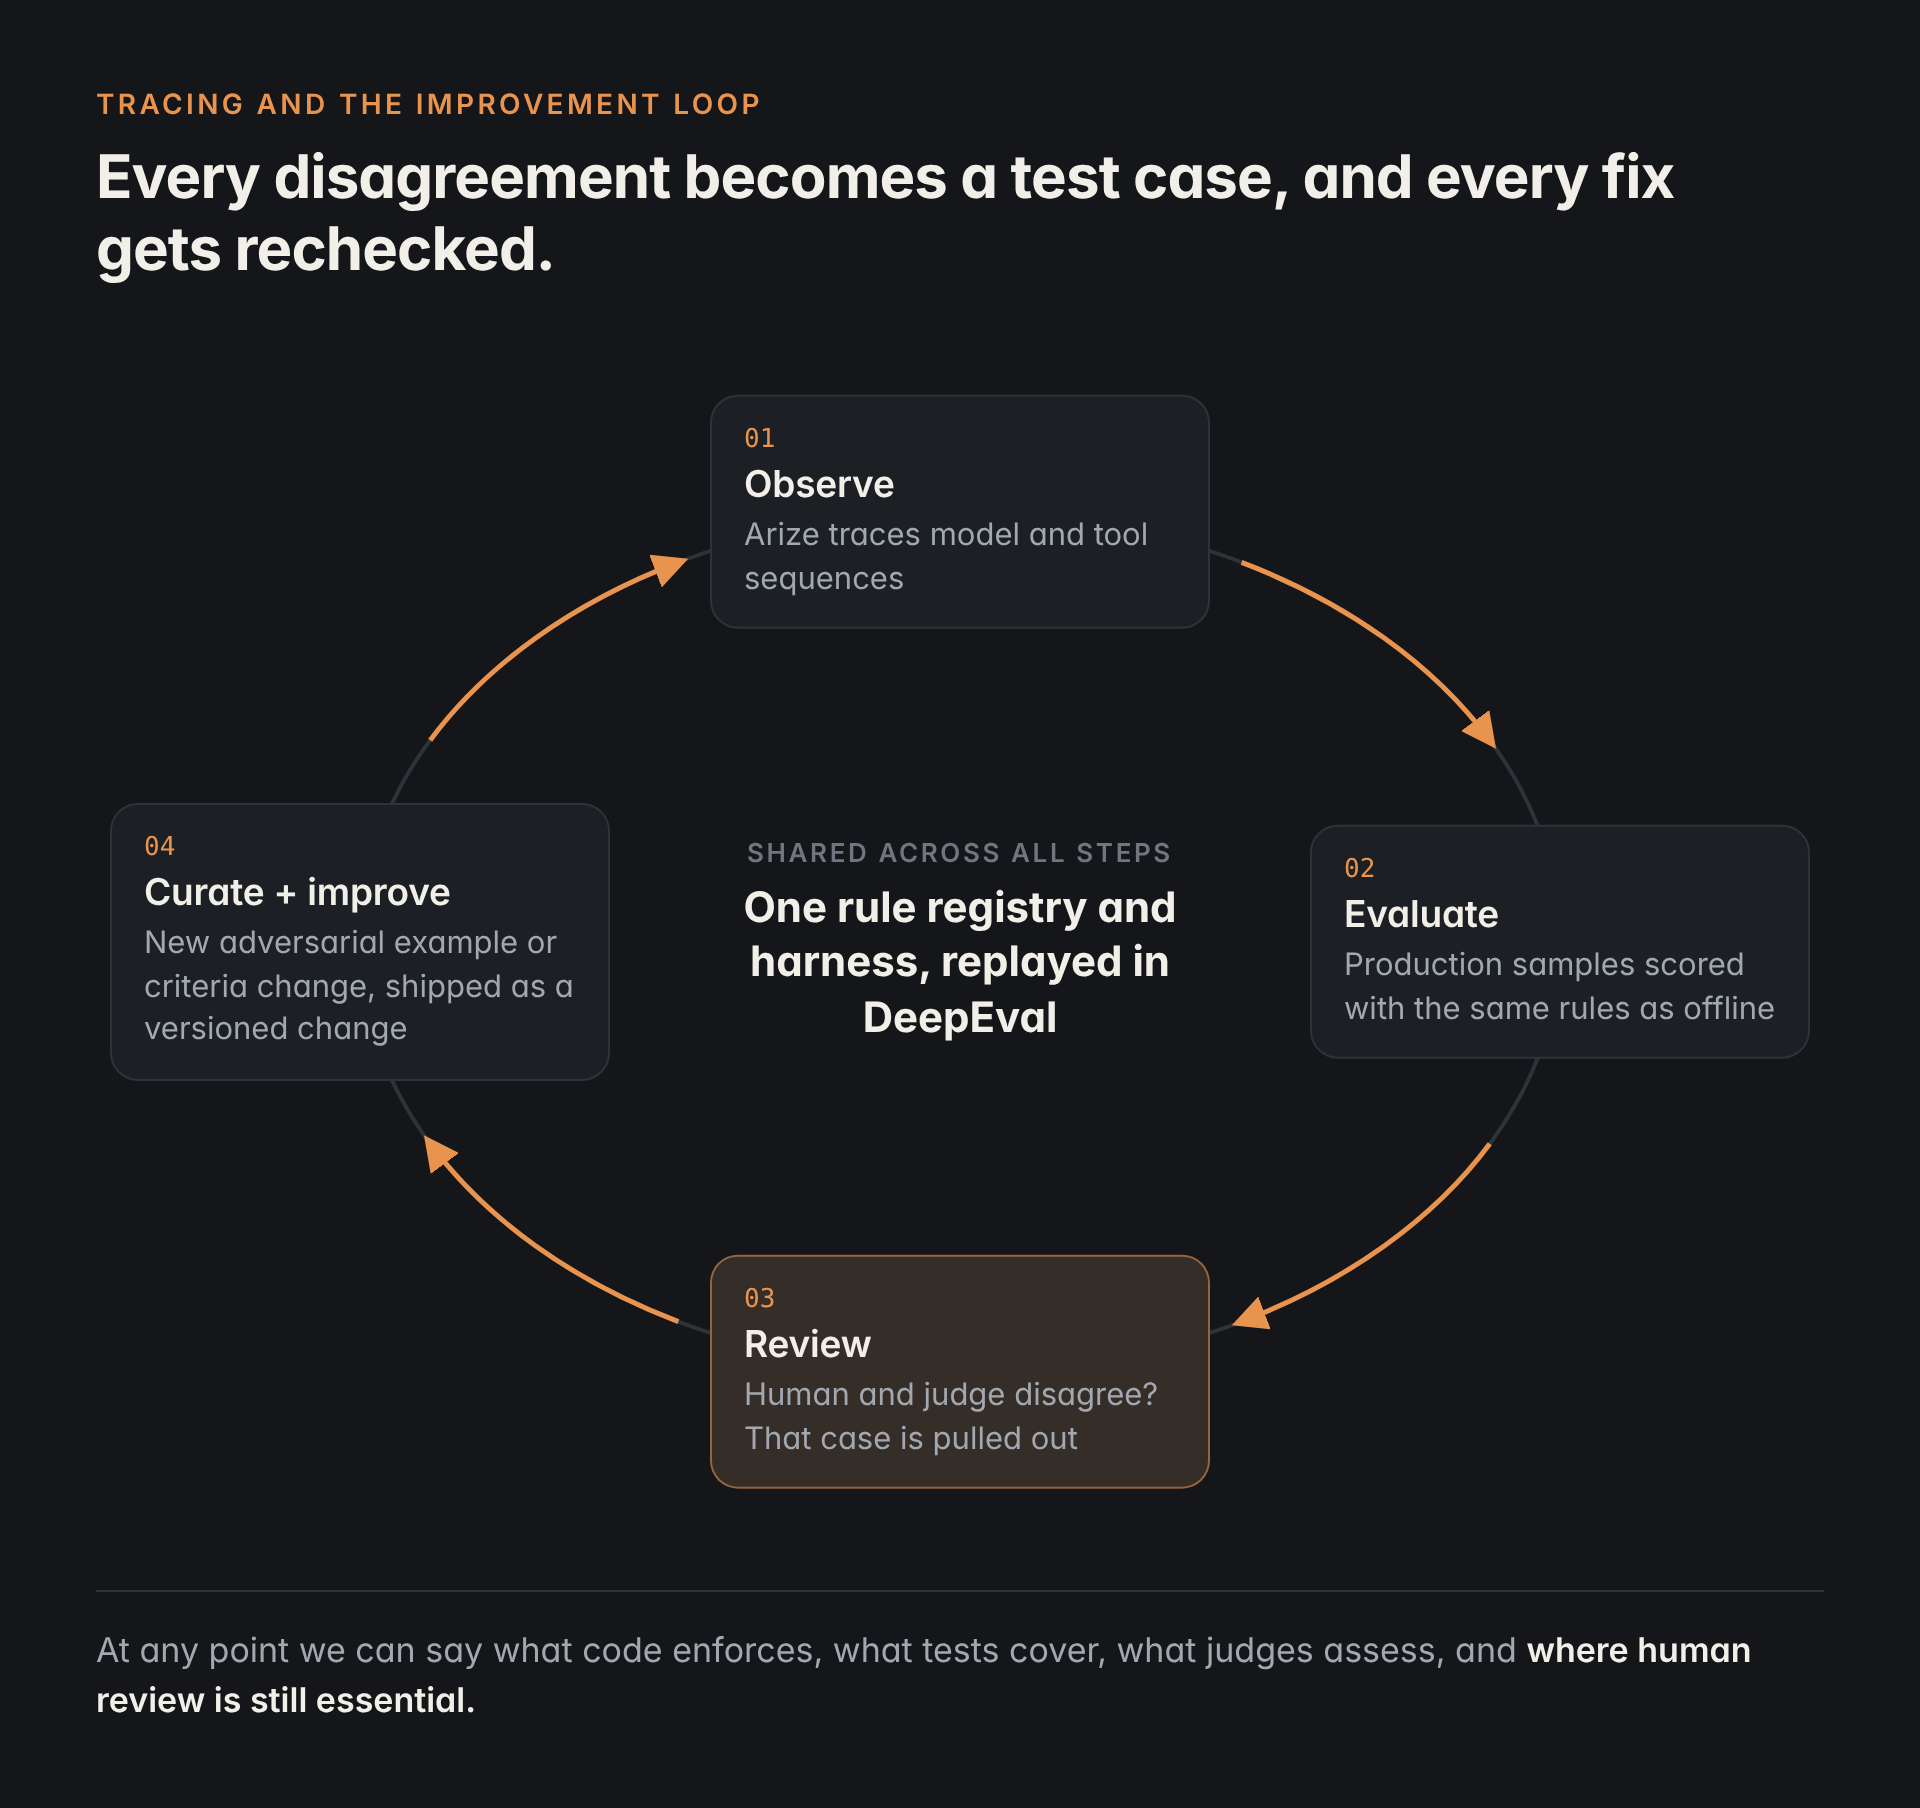
Arize receives traces of model and tool sequences, prompt-selection metadata, and evaluation results. Sampled production traces are scored with the same rule registry and compiler used offline. This is downstream monitoring and review, separate from inline enforcement on each request.
When a human reviewer and a judge disagree, the case can become a new adversarial example or a criteria change. It’s then replayed through the shared harness and DeepEval, alongside deterministic behavior checks, per-dimension verdicts, and graded agent scores, each kept as a distinct signal.
Improvements land as reviewable changes to prompts, playbooks, tools, criteria, and datasets. At any point we can say what application code enforces, what deterministic tests cover, what judges assess, and where human review is still essential.
Trace the workflow. Review the failure. Improve the system. Keep the evidence.
The roadmap
The next capabilities build on the same permissions, evidence, and evaluation framework.
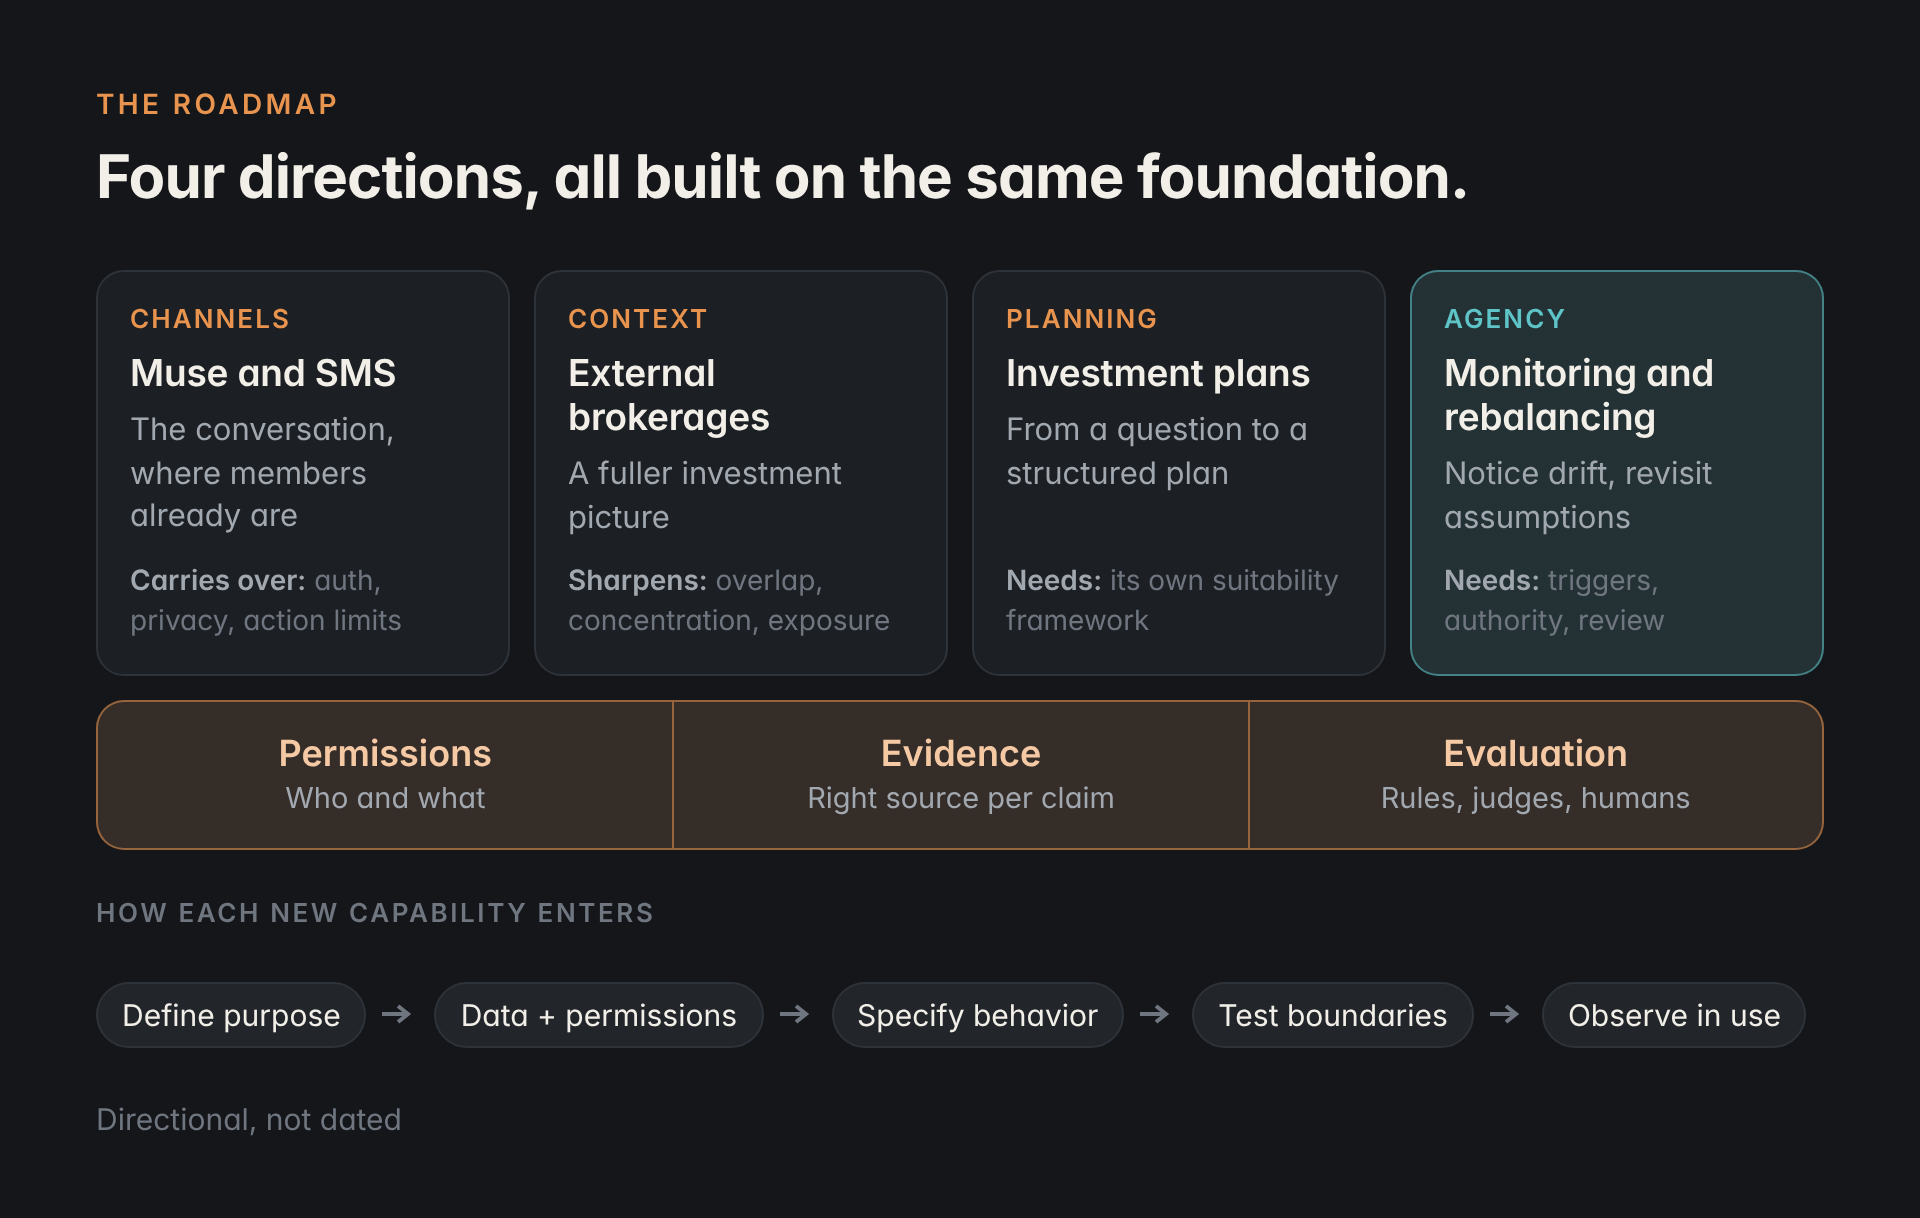
Muse integration and an Instinct-like SMS experience will bring more of the conversation into the channels members already use. Authentication, privacy, and action boundaries carry across every surface.
External brokerage linking will help Arlo understand more of a member’s investment picture. Concentration, overlap, and exposure become more meaningful once the context extends beyond one account.
Investment plans for new and existing members are another direction. Moving from a question to a structured plan needs its own product design, suitability framework, and evaluation coverage.
Agentic monitoring and rebalancing will extend the system further: noticing relevant changes, understanding drift, revisiting assumptions, and reviewing potential adjustments. That work needs explicit triggers, appropriate evidence, defined authority, and clear review and execution boundaries.
Each new capability follows the same path into the system: define its purpose, establish its data and permissions, specify its behavior, test its boundaries, and observe it in use.
Images were generated using ChatGPT and Claude. Content was reviewed with Claude.
Frequently asked questions
What is Arlo and why was it built?
Arlo is an AI financial assistant designed to provide personalized investment advice. It was built to democratize expert investing, making financial wisdom accessible to those who can't afford a wealth manager.
How does Arlo differ from Claude Opus?
While Arlo runs on Claude, it is enhanced with account data, suitability checks, and compliance with financial regulations, providing personalized advice that Claude alone cannot offer.
What problem does Arlo aim to solve for investors?
Arlo addresses the diverse questions investors have about their portfolios by providing insights, recommendations, and market intelligence, all personalized to their financial context and needs.
How does Arlo handle investment recommendations?
Arlo uses a backend evidence pipeline to match investment themes and suitability, providing recommendations based on investor profiles, risk data, and account context, without inventing risk tolerance.
What role does compliance play in Arlo's operation?
Compliance ensures Arlo's recommendations adhere to investment obligations and regulatory standards, using rule packs, judges, and human review to evaluate and validate the advice given.
About the author
- 20+ year builder. CTO @ dub. Building AI investing products.